Using OpenTofu to manage your Infrastructure as Code
In the Django Commons organization we use OpenTofu to manage our Infrastructure as Code (IaC).
While we have done this since the very beginning (though we initially started with Terraform instead of OpenTofu), I was always a bit unsure as to what is actually happening. I decided the best way to understand it was to just dive in, head first, and use it for some of my own personal infrastructure.
OpenTofu is an open source forked alternative to Terraform version 1.5.6. Why an open source alternative? HashiCorp changed the license from Mozilla Public License (MPL) 2.0 to the Business Source License (BSL) on August 10, 2023. For more, read their Manifesto.
Start with what you want to manage
The easiest way to understand OpenTofu is to start with the thing you want to manage and work backwards. At Django Commons that's things like the members and teams of our GitHub organization. For me, it was the servers, firewalls and DNS records I have on Hetzner (and, eventually, a handful of other services).
Once you know what you want to manage, you can work out what OpenTofu needs to manage it:
- A provider to talk to the service
- The resources you want it to manage
- Somewhere to keep state, the record of what it manages
- Variables (and maybe outputs) for the values that change or are secret
Modules come last, once there's enough that you want to break it into smaller pieces.
Provider
Providers are connectors. Each one is a plugin that lets OpenTofu create, read, update, and delete resources on a given platform (AWS, GitHub, Hetzner, etc). You write your configuration in a consistent way, and the provider takes care of talking to that platform's API for you. There are a LOT of providers.
For Django Commons managing GitHub members, that's the github provider. For my Hetzner servers, it's the hcloud provider.
Resource
Resources are the actual things you're managing ... users, servers, DNS records, firewalls, etc. Per the docs:
In summary, applying an OpenTofu configuration will:
- Create resources that exist in the configuration but are not associated with a real infrastructure object in the state.
- Destroy resources that exist in the state but no longer exist in the configuration.
- Forget resources that exist in the state but no longer in the configuration and are referenced in a
removedblock within the configuration.- Update in-place resources whose arguments have changed.
- Destroy and re-create resources whose arguments have changed but which cannot be updated in-place due to remote API limitations.
Each resource type is implemented by a provider. You can also change how OpenTofu treats a resource with a lifecycle block. Some of the arguments it takes:
create_before_destroy: does what it says, but there are some limitations depending on the API you're interacting withprevent_destroy: stops OpenTofu from destroying the resource. You'll see me use this below when I set up Hetznerignore_changes: useful for things that might change outside of OpenTofu. The example in the docs is tags that get added to a resource at the sourceenabled: when set tofalse, OpenTofu acts as if the resource isn't in the configuration at all. If it's already in state, that means it gets destroyed. It's tempting to compare this tomanaged = Falsein Django, but that's nearly the opposite: Django leaves an unmanaged table alone, while OpenTofu deletes a disabled resourcedestroy: when set tofalse, removing the resource from the configuration makes OpenTofu forget it (drop it from state) instead of destroying the real thing. It works like aremovedblockpreconditionandpostcondition: these "can help capture assumptions, helping future maintainers understand the configuration design and intent" per the docs
A few other things that stood out:
- You can set operation timeouts
- You might get deprecation warnings
terraform_datais confusing. I asked Claude to explain it, and what made it click was this:replace_triggered_byonly works with resources, so you can't point it at a plain variable or local.terraform_datawraps a plain value in a resource, so changing that value can trigger a replacement. It's also handy as a do-nothing container for provisioners when there's no other resource that makes sense to hang them on.
One last thing on resources. Provisioners run a script or copy files onto a machine after OpenTofu creates it. They should be used as a last resort, and the docs suggest using cloud-init instead.
State and backend
State is how OpenTofu remembers what it manages. Its primary purpose is to store the bindings between objects in a remote system and the resources declared in your configuration. When you run tofu plan, OpenTofu compares three things: your configuration, the state, and what actually exists.
The backend is where that state lives. If you don't configure one, it's a terraform.tfstate file in the directory you run tofu from. That's fine for trying things out, but it means the state only exists on your laptop.
Where to keep state was one of the bigger decisions at Django Commons. We started with the state file stored on GitHub, and then Daniel and Tim set up an AWS backend so that everyone on the team works from one shared state file.
For my own infrastructure I started with local state, and then moved it to an S3 backend. Every directory (root module) gets its own state file in the same bucket:
terraform {
  backend "s3" {
    bucket       = "ryancheley-tofu-state"
    key          = "hetzner/terraform.tfstate"
    region       = "us-west-2"
    use_lockfile = true
  }
}
The bucket is versioned, so a bad state write can be undone by restoring an older version, and use_lockfile = true stops two runs from writing state at the same time. Changing the backend means running tofu init -migrate-state, which copies the existing state to the new location.1
A couple of other things on state:
importis how you bring in existing resources. This is what I ended up using for my own infrastructure- Workspaces let one configuration have more than one state. Despite what a video I watched implied, they aren't meant for separate environments (separate directories like
envs/prodandenvs/stagingare). Neither Django Commons nor I use them
The terraform_remote_state docs look scary at first. I initially read them as a lot of "You can do this, but you shouldn't." The concern is that terraform_remote_state exposes the entire state file, which can include secrets that another team maybe shouldn't have access to. This is one of those questions of: will my current setup ALWAYS be just me and NEVER change? If the answer is yes, then this is a perfectly acceptable way to proceed ... but remember, ALWAYS and NEVER are very long times.
Variable
Input variables are like function arguments. Some things I learned about them:
- You can add a description which acts like a doc string for the variable
- Setting
sensitive = truewill keep the value out of theplanandapplyoutput - Be careful though ... errors can leak these sensitive values
- Ephemeral variables are available by setting
ephemeral = true
I wasn't sure when I'd use an ephemeral variable instead of a sensitive one, so I asked Claude. Ephemeral variables are for secrets that OpenTofu needs while it runs but should never write down. Their values aren't stored in state at all, and only the variable names are saved in the plan. A sensitive value, on the other hand, is still stored in state and in saved plan files. Only the display is masked. I had assumed they did the same thing!
You can set variables individually on the command line, or put them in a *.tfvars file to read from. This feels a lot like docker with flags vs. docker compose with a docker-compose.yml file. OpenTofu will also automatically load variable definition files if they're present:
- Files named exactly
terraform.tfvarsorterraform.tfvars.json - Any files with names ending in
.auto.tfvarsor.auto.tfvars.json
If the same variable is assigned more than once, OpenTofu uses the last value it finds. See the docs for the full precedence order.
Output
Per the docs:
Output values make information about your infrastructure available on the command line, and can expose information for other OpenTofu configurations to use. Output values are similar to return values in programming languages.
You can use precondition and postcondition here too, and there's a depends_on key that works a lot like it does in docker compose.
Module
Modules are how you group resources together, and they're what you reach for once a configuration gets big enough that you want to break it into smaller pieces. Every OpenTofu configuration has at least one module, known as its root module. This is just the resources defined in the .tf or .tofu files in the directory you're running tofu from. For my own setup, each provider gets its own directory, so each one is its own root module with its own state.
Here's what grouping looks like. A web_server module could bundle a server with the firewall it always needs:
# modules/web_server/main.tf
variable "name" {
  type = string
}

resource "hcloud_firewall" "this" {
  name = "${var.name}-fw"

  rule {
    direction  = "in"
    protocol   = "tcp"
    port       = "443"
    source_ips = ["0.0.0.0/0", "::/0"]
  }
}

resource "hcloud_server" "this" {
  name         = var.name
  server_type  = "cx22"
  image        = "ubuntu-24.04"
  firewall_ids = [hcloud_firewall.this.id]
}
Then each new server is a few lines in the root module:
module "blog" {
  source = "./modules/web_server"
  name   = "blog"
}

module "status_page" {
  source = "./modules/web_server"
  name   = "status-page"
}
A couple of things I noticed:
- Only provider configurations are inherited by child modules, not provider source or version requirements. Each module has to declare its own provider requirements. This is especially important for non-HashiCorp providers.
- When you've outgrown your initial configuration, check out Refactoring in the docs
Using OpenTofu to manage my own infrastructure
To help solidify what I'd learned, I decided to use OpenTofu to manage my own infrastructure. For that I used the following providers:
- AWS
- Coolify
- DigitalOcean
- GitHub
- Hetzner
- Tailscale
In my case I'm importing what I already have, not adding new things (yet!).
Here's a quick walkthrough of setting up Hetzner with OpenTofu:
- Created an
infradirectory, and then ahetznerdirectory inside of it - Created
main.tfand added the Hetzner provider - Ran
tofu init - Created
imports.tfto catalog all of the infrastructure I wanted to import - Ran
tofu plan -generate-config-out=generated.tf, which createdgenerated.tf. I did have to set theHCLOUD_TOKENenvironment variable first withset -x HCLOUD_TOKEN (op read "op://token-location")2 -
Updated each server with a
lifecycleblock to prevent any accidental destruction:lifecycle { ignore_changes = [image, user_data, ssh_keys] prevent_destroy = true } -
Ran
tofu applyto bring everything into state - Later, moved the state from a local file to the S3 backend described above
Some caveats:
- For Hetzner, make sure every server has
prevent_destroy = true(see step 6 above). You do NOT want a typo to delete a server - For Tailscale, import your ACL policy and use
tailscale_devicedata sources for your machines (all ten in my case). Be careful though ... a bad policy can lock you out of your machines3 - Don't let Coolify create Hetzner servers, as they will collide with the
hcloudprovider
Encrypting my state
This part is specific to my setup. Django Commons doesn't encrypt its state (we use 1Password there to manage access to AWS).
State holds everything OpenTofu knows about your resources, and depending on the provider that can include secrets, so I wanted mine encrypted. OpenTofu has native state encryption built in, which is one of the things it has that Terraform doesn't. I added an encryption block to the terraform block:
terraform {
  encryption {
    key_provider "pbkdf2" "main" {
      passphrase = var.state_passphrase # at least 16 characters
    }
    method "aes_gcm" "main" {
      keys = key_provider.pbkdf2.main
    }
    state {
      method   = method.aes_gcm.main
      enforced = true
    }
    plan {
      method   = method.aes_gcm.main
      enforced = true
    }
  }
}
Along with a state_passphrase variable (marked sensitive). The passphrase lives in 1Password, and I pass it in as TF_VAR_state_passphrase with op run. enforced = true means OpenTofu will refuse to write state or plans unencrypted.
This was a pita because I had already imported everything, so my state file was sitting there unencrypted, and OpenTofu won't read it once you've told it everything should be encrypted. To migrate it I had to:
- Back up
terraform.tfstate(just in case!) - Remove
enforced = truefor now. While it's set you get "Unable to use unencrypted method since the enforced flag is set." - Add a temporary
method "unencrypted" "migrate" {}and afallback { method = method.unencrypted.migrate }inside bothstateandplan. This lets OpenTofu read the plain state one last time - Run
tofu apply -refresh-only, then check withgrep -c encrypted_data terraform.tfstate. If it prints 1, the state is encrypted - Remove the
unencryptedmethod and bothfallbackblocks, putenforced = trueback, and make suretofu planreports "No changes"
A few gotchas:
- Plain
tofu initstops working. The encryption block needs the passphrase, so eveninithas to run throughop run - Don't lose the passphrase! Without it, the state is unreadable. Same goes for removing the
encryptionblock later ... treat it as permanent - Keep the passphrase in its own 1Password item. If you add it as an extra field on, say, the Hetzner API token's item, then replacing that item when you rotate the token takes your state key with it
If I were doing this again (which I did for every other provider after Hetzner), I'd turn encryption on before the first import and skip the whole migration dance.
Does the order of the files matter?
As things evolved, I refactored from having just main.tf and generated.tf to having the following *.tf files:
dns.tffirewalls.tfprimary_ips.tfproviders.tfrdns.tfservers.tfssh_keys.tfvariables.tfversions.tfzones.tf
Each one is named for the resources it's managing. This led me to wonder:
When I run
tofu planortofu apply, what order do the*.tffiles get processed in? Does it matter what I name them?
I did some research, and also asked Claude. Names don't affect the order. OpenTofu loads every .tf file in the directory, merges them into one configuration, and then works out the order from the references between blocks.
A little more detail on how that works:
- When you run
tofu planortofu apply, it reads every.tfand.tf.jsonfile in the current directory. It does NOT read subdirectories - It reads the files alphabetically, but that has no effect on the result. All of the blocks are merged as if they were in one file
- It then builds a dependency graph from the references between blocks. If
hcloud_server.webp1useshcloud_firewall.firewall.id, the firewall is handled first, no matter which file each one is defined in. Resources that don't depend on each other run in parallel, 10 at a time by default - If the graph misses a dependency, you add
depends_on. My Tailscale config does this so the ACL is applied before the auth key. Renaming or reordering files will never fix ordering
Here's the overall flow of a tofu plan or tofu apply:
flowchart LR
    load["1 · Load and merge<br/>every .tf file"] --> readstate["2 · Read state<br/>from the backend"]
    readstate --> deps["3 · Build the<br/>dependency graph"]
    deps --> plan["4 · Plan: compare<br/>config, state, reality"]
    plan --> apply["5 · Apply changes,<br/>write state back"]
This is also why, when I moved my state bucket's configuration from main.tf into s3.tf as part of my refactor, the plan showed no changes. A resource's address (aws_s3_bucket.resource_name) is the same no matter which file it's in.
That said, there are a few cases where file names DO matter:
- Override files: files named
override.tfor ending in_override.tfare loaded last. Their blocks are merged into blocks with the same name instead of being treated as duplicates. Avoid these unless you really mean to use them .tofufiles: OpenTofu also reads.tofuand.tofu.jsonfiles. Iffoo.tofuandfoo.tfboth exist, it usesfoo.tofuand ignoresfoo.tf- Test files:
.tftest.hcland.tofutest.hclfiles are only used bytofu test - Ignored files: editor temp files (names ending in
~or wrapped in#...#) are skipped, as is any other extension. My Tailscalepolicy.hujsononly gets read because I load it withfile() - Duplicates: a block defined twice is an error, no matter which files the two copies are in
A checklist for adding a new provider
After doing this for six providers, I wrote up a checklist so the next one doesn't involve rediscovering the same gotchas. It assumes you're adopting infrastructure that already exists, and that each provider gets its own root module with its own state. Each section starts with its Bail out criteria, so you can stop before doing work you'll throw away.
tofu commands run through op run --env-file=.env --, which is 1Password's runner; use your own secrets manager's equivalent.
1. Discover what exists
Bail out if the account is empty and you don't want a placeholder module, or if the account isn't yours. Infrastructure that belongs to an employer or an organization you volunteer for goes in that organization's repo.
Take inventory
- Check that your local credentials still work. A CLI that returns 401 may have a stale token, so get a fresh one before concluding anything.
-
List every resource type with read-only calls. Use the service's CLI or API, or the provider's own list data sources in a temporary
discover.tfwith anoutput. For Hetzner:data "hcloud_servers" "all" {} output "servers" { value = [for s in data.hcloud_servers.all.servers : { id = s.id, name = s.name }] }Run
op run --env-file=.env -- tofu apply(it only adds the output), thentofu output -json servers. Keep the output to IDs and names like this, and mark itsensitive = trueif you need fields that hold secrets. Deletediscover.tfafterwards; its outputs stay in state until the next apply removes them. - Note IDs, names, and how each resource relates to others (which project, server or app it belongs to). Note which resources are defaults the service creates for you.
Decide what to manage
- Skip defaults the service won't let you delete (default VPCs, default projects), empty accounts and leftover test resources. Records the service manages itself, like DNS
SOAandNSrecords, stay out too. - Decide which tool owns each resource. Two providers managing the same thing fight each other. For example, if one provider creates your servers, a deployment platform's provider should only register them. Resources another system creates become
datasources. - Note anything the provider can't manage, such as OAuth clients, consent screens or key material. Those stay manual, or you reference them as
datasources. Bare-metal hardware and what runs inside machines belong to a configuration tool like Ansible.
2. Vet the provider
Bail out if the important resources can't be imported, Read only checks that the resource exists, or the provider is unmaintained. Check these first:
- Find it on search.opentofu.org. If it isn't there, check the Terraform registry or search GitHub for
terraform-provider-<name>. A service with no public API can't have a provider. - Check maintenance: last release, last commit, open issues, and whether the repo is archived.
- Check import support in the provider source with
grep -rln ImportState --include='*.go'. The docs often leave it out. - For the resources that matter most, read
ImportStateandRead:- Does
ImportStateset every attribute thatReadneeds, such as the name? - Does
Readrefresh attributes, or only check that the resource exists? If it only checks existence, OpenTofu can't detect drift. - Does
Readreturn parent IDs (project, server)? If not, imports generate them asnulland you fill them in by hand.
- Does
Then note these, since they shape how you write the config:
- A
replacedirective ingo.modmeans the provider builds against someone's fork. Pin the version of anything pre-1.0. - Check which credentials the provider reads. Environment variables or Tofu variables let you inject them from a secrets manager instead of writing them to disk.
- Check whether the provider has several resource types for the same thing (for example, one per app source). The type has to match how the resource was created, or the plan forces a replacement.
- Check whether the provider offers several ways to express one relationship (for example, attaching a firewall from the server, from the firewall, or with a separate attachment resource). Pick one; two describing the same link cause a permanent diff.
3. Set up credentials
Create the token
- Store the credentials in a secrets manager. Use a dedicated token with the minimum permissions the provider needs. A CLI login token (like
gh auth token) has the access of your whole login and gets replaced when you log in again, which leaves the stored copy stale. - Give the token read access to sensitive fields if the provider compares them. With redacted reads, every plan shows phantom diffs. Avoid root or admin scopes the provider doesn't need.
- If the provider warns about token permissions, work out what the token can actually read. A token that can read config files can read the secrets in them, and imported values land in state. That's a reason to encrypt state.
- Keep the state passphrase in its own secrets-manager item. If it's an extra field on a provider's token item, replacing that item when you rotate the token takes the state key with it.
Use it safely
- Test the credentials once, interactively or with a single API call, before using them from OpenTofu. Don't retry failed logins blindly. Some services, Synology DSM among them, block an IP after repeated failures.
-
Never print secret values. To debug, print only their shape:
op read "op://Private/Example OpenTofu/token" | wc -c # length (+1 for op's trailing newline) op read "op://Private/Example OpenTofu/token" | sed 's/[^[:space:]]/*/g' | cat -et # stray spaces show before the $ -
Don't export credentials in your shell, and never in persistent shell variables (fish universal variables are stored in plain text). Inject them per command with your secrets manager's runner. With 1Password,
op run --env-file=.envreadsop://references from a.envfile (section 4) and resolves them for that one command only. - Remove anything that overrides the environment: a
profile = ...in the provider block, entries in~/.aws/credentials, exported shell variables. Providers prefer those over the injected values. Run the CLI the same way when you need it:op run --env-file=.env -- aws sts get-caller-identity.
4. Scaffold the module
Files
- Create a branch for the work.
- Name the directory after the provider, in lowercase (
hetzner/,digitalocean/). -
Split the config across
versions.tf,providers.tfandvariables.tf. Use the same names in every module, and skipmain.tf, so you always know where to look.versions.tfholds the OpenTofu and provider versions, the backend, and the state encryption. Turn encryption on now, before the first import; migrating existing unencrypted state is the dance from Encrypting my state.terraform { required_version = ">= 1.10" required_providers { example = { source = "example-org/example" version = "~> 1.4" } } backend "s3" { bucket = "my-tofu-state" key = "example/terraform.tfstate" region = "us-west-2" use_lockfile = true } encryption { key_provider "pbkdf2" "main" { passphrase = var.state_passphrase } method "aes_gcm" "main" { keys = key_provider.pbkdf2.main } state { method = method.aes_gcm.main enforced = true } plan { method = method.aes_gcm.main enforced = true } } }providers.tfholds the provider blocks. Leave them empty and let credentials come from the environment:provider "example" {}variables.tfholds every variable, starting with the passphrase:variable "state_passphrase" { type = string sensitive = true }Each module uses the same bucket with its own
key. Pin the provider with~>to the major and minor version you install, so a new release can't change behaviour without you noticing. -
Add one aliased
providerblock per extra region (for AWS, a secondprovider "aws"withalias = "use1"andregion = "us-east-1"). A resource in another region needsprovider = aws.use1on both its import block and its resource. - Keep
required_providersand each defaultproviderblock in exactly one file. A second copy is a "Duplicate provider configuration" error.
Secrets
-
Create a gitignored
.envthat holdsop://references, not the secrets themselves.op runresolves them at run time (see section 3):EXAMPLE_TOKEN=op://Private/Example OpenTofu/token TF_VAR_state_passphrase=op://Private/OpenTofu State/passphraseIf a
.envalready exists, add to it instead of overwriting it. Tools like direnv may also load a file named.envand set the literalop://strings as values. - Make sure.gitignorecovers.env,.terraform/,*.tfstate,*.tfstate.*and*.tfplan.
First run
op run --env-file=.env -- tofu init, thentofu fmt -check && tofu validate.initneedsop runtoo: the encryption block reads the passphrase variable, and without it init fails with "depends on var.state_passphrase which is not available". Re-runinitwheneverrequired_providers, the backend or encryption changes;init -upgradeto move to a newer provider version.op run --env-file=.env -- tofu planshould report "No changes". An empty plan doesn't log in, so the first import is the real auth test.- Prove the plan uses only the secrets manager: unset exported variables (
env -u VAR), hide CLI config files (AWS_SHARED_CREDENTIALS_FILE=/dev/null), and block CLI fallbacks (GH_CONFIG_DIR=$(mktemp -d)stops the GitHub provider using yourghlogin). - Commit
.terraform.lock.hclso every machine installs the same provider version.
5. Import resources
Bail out if the plan wants to replace or modify resources you can't safely ignore, or if the provider errors on import. Delete imports.tf and check with tofu state list that nothing was written to state.
Write the import blocks
-
Write
imports.tfwith oneimport {}block per resource:import { to = example_ssh_key.laptop id = "12345678" }Check the import ID format in the provider's
ImportState, because it may be a numeric ID, a UUID, a name or a composite (such aszone/name/typefor DNS record sets). - Pick resource names (the label after the type) by one rule and stick to it: -thisfor singletons the account has only one of (an ACL, DNS preferences). - Otherwise, the snake_case form of the real-world name, soexample_bucket.my_backupsfor a bucket calledmy-backups. Avoid nicknames and generic labels likeserverorfirewall; they stop making sense once there's a second one. - DNS records:<zone>_<record>_<type>, such asexample_www_cname.Names are hard to change later: renaming one in state takes a
moved {}block. - For many resources, generate the import blocks with a loop over the CLI's list output. Resource names can't contain dots,@or*, or start with a digit, so sanitize them (a prefix liker_, punctuation to_). - Start with low-risk resources and do one resource type at a time. Leave production resources (servers, VMs) until the low-risk imports come back clean.
Generate the config
- Run
op run --env-file=.env -- tofu plan -generate-config-out=generated.tf, but don't apply yet. - The output file must not already exist, and OpenTofu writes it even when the plan fails. If the plan errors, edit
generated.tfto fix the errors and run a plaintofu plan, rather than deleting it and generating it again. - If an import fails with "Cannot import non-existent remote object", the provider is looking in the wrong place: check the resource's region, the provider alias, and which account the credentials belong to (
aws sts get-caller-identityfor AWS). If those are right, plan again; it can be transient. - Commit the generated config before editing it with a script, so the edit is easy to review and undo.
Clean up the generated config
- Remove empty strings (
"") that fail validation. - Remove computed or read-only attributes.
- Remove one of each pair of mutually exclusive attributes the generator writes together (AWS S3 buckets get both
bucketandbucket_prefix). - Look for stale values, such as an old download URL or version, that would change the real resource if applied.
- Fill in parent IDs that came back
nullby looking them up in the service's API, and add them toignore_changes. Some force replacement if they differ. - Remove sensitive fields (webhook secrets, passwords) and add them to
ignore_changes. A generatednullwould wipe the real value on apply. - Leave config that contains literal secrets (like a compose file with a password in it) in the source system: use a placeholder value and
ignore_changes. - Set JSON-string attributes to the exact string the API returns.
jsonencode()sorts keys, which shows up as a diff when the provider compares raw text. - Give read-only resources (archived GitHub repos, for example)
lifecycle { ignore_changes = all }. The API rejects updates to them anyway. - If an attribute the provider fills with a default would cause a diff, put it in
lifecycle { ignore_changes = [...] }with a comment explaining why. For each ignored field, the service's UI is now the source of truth. - Split the config into one file per resource type, named in plural snake_case (
ssh_keys.tf,projects.tf, …). Delete the# __generated__header comments, runtofu fmt(generated config isn't always formatted), and deletegenerated.tf.
Plan and apply
- Plan again. With many resources, group the remaining diffs by attribute to see which fixes clear the most, and check whether the drifting resources share something, such as all being archived.
- Apply only when the plan shows N to import, 0 to add, 0 to change, 0 to destroy, with no "must be replaced" lines.
- If the plan shows resources "to add" that you know exist, OpenTofu isn't reading your state (wrong workspace, missing or unreadable state file). Don't apply; it would create duplicates.
op run --env-file=.env -- tofu apply- Delete
imports.tf. After the apply, the resources are in state and the import blocks do nothing. tofu planshould report "No changes".
6. Change and clean up (optional)
Before you start
- Run
tofu planand deal with any pending changes first so they don't mix with yours. - Protect resources you can't lose with
lifecycle { prevent_destroy = true }, plus the service's own protection where it exists (such as Hetzner'sdelete_protection). Turn off settings that delete resources as a side effect, such as auto-delete on IP addresses. Removing a resource block from config destroys the resource.
Making changes
- Swap hardcoded IDs and IPs for references to other resources. The plan should still show no changes.
- To rename a resource that's already in state, add a
moved {}block instead of a new import. - Some settings aren't standalone objects (reverse DNS is often a setting on an IP), so there's nothing to import; you create the resource and it overwrites the current value.
- Don't change the same object twice in one apply. Some APIs run one action per object at a time and reject the second with a 409 conflict. A failed apply may still have made the change, so check the service, then import the resource instead of creating it again.
- If an apply hangs, press Ctrl-C once so OpenTofu releases the state lock. Pressing it twice can leave the lock behind.
- After changing access control (ACLs, tags, firewall rules), test the systems that depend on it, not just the plan. In Tailscale, for example, tagging a device removes it from
autogroup:member, so rules that allowed members stop applying to it.
Deleting things
- To delete a resource that's now managed, remove it from config and run plan. Read the destroy plan before applying, because deletes can't be undone. Check what's inside first; a bucket may hold another project's state.
- Delete config files that are now empty.
7. Document and ship
- Add the module to your README: what it manages and which environment variables its
.envneeds. - Write down the provider quirks you hit (ignored fields, defaults you left unmanaged, import gotchas) so the next import doesn't rediscover them.
tofu fmt -checkin the module.- Commit, open a pull request, and merge once checks pass.
If you'd rather see it as a picture, here's the whole process as a flowchart.
Conclusion
This was one of those processes where I ended up going really deep down a rabbit hole or two. BUT, I did learn a lot and now feel more comfortable with the OpenTofu process within Django Commons, which was my goal at the start.
Thanks
A big thank you to Daniel Moran and Tim Schilling for reviewing an earlier draft of this post. Their feedback was invaluable. Any mistakes that remain are my own.
- There's a fun chicken-and-egg problem here: the bucket itself is managed by my
awsmodule, which also keeps its state in that bucket. If the bucket ever disappears, theawsmodule has to fall back to local state long enough to recreate it. ↩︎ - I did get a scary warning: "Note: You didn't use the -out option to save this plan, so OpenTofu can't guarantee to take exactly these actions if you run "tofu apply" now." It seems to be directed more at teams, where something may change between the
planand theapply. Since it's just me, there's little risk here. ↩︎ - I actually saw this manifest on my Coolify server when it couldn't reach any of the servers via Tailscale any longer. It was a quick fix, but there was a bit of "Oh SHIT!" when Coolify stopped being able to interact with my hetzner servers! ↩︎
Atuin - The Magical Shell Tool
In part two of my series, "Learning on Leave" I spent some time going through the docs for Atuin. I even went down a rabbit hole of rolling my own sync server!
What is Atuin and why would I use it?
Atuin is "Shell history supercharged". Per their website:
Sync, search, and back up your shell history with end-to-end encryption. The magical shell tool loved by developers worldwide.
I first learned about it on Mastodon from b0rk. As an aside, she's also where I first learned about fish which is a great shell!
It's been a real game changer for me. Logging into different servers and having access to my shell history across all machines is kind of a game changer.
Things I learned
ctrl-r
When I migrated from just the standard zsh history to Atuin, I was just used to using ctrl-r to search, but Atuin offered use of the up-arrow key to browse through my history. This seemed easier to me, so I started to use that exclusively and then completely forgot that ctrl-r ever existed 🤦🏻♂️
The thing is, ctrl-r will also allow you to cycle through the filter modes (global, host, session, directory, workspace, session-preload). This allows you to see all commands, or focus on just the session history. You can update the settings to have the history set to a specific filter mode. The default is global which means all of the synced history from all servers. After learning about this I decided to update mine to host.
See the docs for more on filter mode.
See the docs for more on workspaces
ctrl-o
While you're in the history (using ctrl-r) you can use ctrl-o to show you the history of that command. The history is limited by what your filter mode is. If you set it to host it will only show the history of that command on the host you're currently on
- Agent integration
There is agent integration via atuin hook install claude-code and/or atuin mcp install claude-code.
Using atuin hook install claude-code allows Atuin to capture commands that your agents are running. Atuin tags these so they are easy to search on or filter out.
If you want to use atuin mcp install claude-code you will need to have your sync server set to Atuin's sync server, or, if you decided to roll your own sync server, you'll need to set up a self hosted agent server too.
See the docs for more details.
See the docs for more details.
- Deduplicating your history
There is a command that will dedup your history to clean it up if needed. Why would you want to do this if the point of Atuin is to have all of your history? It can be super helpful after you've imported your history, or if a runaway script polluted your history. There are other use cases too I'm sure. But just knowing it's there in case it's needed is pretty nice.
An example would be
atuin history dedup --dry-run --before "2025-01-01" --dupkeep 1
This would perform a dry run of what would be removed for anything from before January 1, 2025. It would only keep 1 copy (the most recent) in history.
To perform the deduplication
atuin history dedup --before "2025-01-01" --dupkeep 1
See the docs for more details.
- Themes
Like many (all) developer tools, we have an ability to express ourselves through themes. The default, "default" is fine, but I prefer Dracula styled themes. There isn't a library of themes, but there are good docs on how to create your own theme.
My Dracula theme looks like this:
[theme]
name = "dracula"

[colors]
Base = "#f8f8f2"          # Dracula Foreground
Muted = "#6272a4"         # Dracula Comment/Grey
Title = "#bd93f9"         # Dracula Purple
Important = "#ff79c6"     # Dracula Pink
Guidance = "#8be9fd"      # Dracula Cyan
Annotation = "#6272a4"    # Dracula Comment/Grey
AlertInfo = "#50fa7b"     # Dracula Green
AlertWarn = "#ffb86c"     # Dracula Orange
AlertError = "#ff5555"    # Dracula Red
And is placed in ~/.config/atuin/themes/dracula.toml.
I then updated my config.toml with this block
[theme]
name = "dracula"
atuin info
The command atuin info shows the location of config files on your system. When I run it on my local macBook Pro I get
Config files:
client config: "/Users/ryan/.config/atuin/config.toml"
server config: "/Users/ryan/.atuin/server.toml"
client db path: /Users/ryan/.local/share/atuin/history.db
key path: /Users/ryan/.local/share/atuin/key
meta db path: /Users/ryan/.local/share/atuin/meta.db

Env Vars:
ATUIN_HOME = None
ATUIN_CONFIG_DIR = None

Version info:
version: 18.24.3
commit:  4532ceacd860885c2310ab8fab92a1bc00d6d7e8
This command can be especially helpful when you're trying to figure out why your config.toml isn't applying your settings the way you expect. In my case, the default one from the atuin install was being used instead of my user one. To fix it I deleted the one set up by atuin. If there are multiple config.toml files you do get a warning when running atuin info so you can see that there is something amiss.
See the docs for more details.
atuin output search
atuin output search allows for cli search capabilities for the output from commands. The command will return the output in addition to the command that prompted the output.
Per the docs:
Matches come back most relevant first, each with its command, when and where it ran, and its output.
you do need to ensure that output capture is enabled.
If it's not, run
atuin config enable output-capture
See the docs for full details.
- Search
The highlight feature of Atuin is its search capabilities and yeah, there's a lot of power in the search.
You can interactively search using a TUI with atuin search -i. This isn't any different than ctrl-r or the up-arrow. BUT if you combine it with a search term, like atuin search -i docker you'll immediately be searching only your docker commands in your history.
There are also some great examples of what's available here
atuin stats
You can run atuin stats to get details on what unique commands you've been running.
For example
atuin stats week --filter-mode session
returns
[▮▮▮▮▮▮▮▮▮▮] 4 cat
[▮▮▮▮▮▮▮   ] 3 clear
[▮▮▮▮▮▮▮   ] 3 grep
[▮▮▮▮▮     ] 2 just
[▮▮▮▮▮     ] 2 atuin
[▮▮        ] 1 wc
[▮▮        ] 1 code
Total commands:   12
Unique commands:  14
Notice that I was able to set the --filter-mode to look only at my session history.
You can also pass time arguments like this
atuin stats last thursday 3pm
This will get you everything since last Thursday at 3pm
atuin store status
The atuin store status command can tell you the status of each machine that has atuin attached to it. The host it displays is a uuid. You can get a pretty hostname, but you need to run
printf '%s %s\n' (cat ~/.local/share/atuin/host_id) (hostname -s)
on each machine.
atuin scriptsTheatuin scriptscommand is currently an undocumented feature. There was a blog post announcing it though.
I continue to struggle with how this is helpful, BUT this doesn't have to be useful for me to be useful in general!
One thing that does look interesting is this invocation:
atuin scripts new script-name --last N --tags my-tag --description "Does the thing!"
This will take the last N commands, add a tag called my-tag and a description Does the thing! and generate a script you can run with atuin scripts run script-name
If you run atuin scripts list you'll get this output
Available scripts:
- script-name [tags: my-tag]
  Description: Does the thing!
This can be especially helpful if you are going to need to do the same thing over and over again (like maybe migrating to a self hosted version of Atuin for all of your servers).
- Key Bindings
This is where we can control, amongst other things, whether or not the up-arrow will invoke Atuin or not. One thing I've been struggling with is that in Herdr the up arrow is captured by a scrolling up mouse as well. This is frustrating for me when I want to scroll up the page output in a shell. I instead have to remember to use the Page-up key instead. I am not a fan.
So, I updated my key bindings to eliminate the up-arrow behavior for Atuin so that the mouse scroll doesn't get stolen by Atuin.
See the docs for full details.
Settings
There are a LOT of settings. Like, holy shit, so many settings!
I'll give a run down of some of the ones that I found most interesting
- sync_address: This is what allows you to have your own self hosted instance. It defaults to "https://api.atuin.sh" so if you don't run your own instance there's nothing you need to update
- filter_mode: this is what allows you to determine which history you start your search in. The default is
global, but I changed it tohost. You can usectrl-rto cycle through the filter_mode though should you need to - inline_height: the default is 40, but I set mine to 15 because I liked the way it looked better. This setting will determine the maximum number of lines Atuin's interface should take up.
- enter_accept: This defaults to
falsebut it kept breaking my brain, so I updated it totrue. When this is set totrue, Atuin will immediately execute a command rather than the user having to press enter twice. Pressing tab returns me to the shell and allows me a chance to edit the command if I want. - theme: allows you to set your theme to a custom theme. I've set mine to
dracula
Rabbit Hole
While working through this I decided that setting up my own atuin sync server would be fun (and maybe easy). Since I use coolify for my various web projects, I decided to use it to stand up my own sync server using the following docker-compose.yml file (created with the help of Claude):
services:
  atuin:
    restart: always
    image: ghcr.io/atuinsh/atuin:62d5bad
    command: start
    expose:
      - 8888
    environment:
      ATUIN_HOST: "0.0.0.0"
      ATUIN_OPEN_REGISTRATION: "true"
      ATUIN_DB_URI: postgres://${ATUIN_DB_USERNAME}:${ATUIN_DB_PASSWORD}@db/${ATUIN_DB_NAME}
      RUST_LOG: info,atuin_server=debug
    depends_on:
      db:
        condition: service_healthy
  db:
    image: postgres:18
    restart: unless-stopped
    healthcheck:
      test: ["CMD-SHELL", "pg_isready -U ${ATUIN_DB_USERNAME} -d ${ATUIN_DB_NAME}"]
      interval: 5s
      timeout: 5s
      retries: 10
    volumes: # Don't remove permanent storage for index database files!
      - "atuin-db:/var/lib/postgresql"
    environment:
      POSTGRES_USER: ${ATUIN_DB_USERNAME}
      POSTGRES_PASSWORD: ${ATUIN_DB_PASSWORD}
      POSTGRES_DB: ${ATUIN_DB_NAME}
      TZ: America/Los_Angeles
      PGTZ: America/Los_Angeles

volumes:
  atuin-db:
There is one limitation with rolling your own sync server. If you want to use the AI features of Atuin you need to roll your own AI server too. They do have a setup guide for that, but it seemed like a solution to a problem I don't have, so I decided against it.
Have you heard the good news about just?
Because of my current cancer treatment I'm on medical leave from work. I spend a LOT of my day resting, or doing very non-active things ... like watching TV Shows. I'm currently binging Star Trek: Strange New Worlds and it's really good.
In order to help stave off brain rot I decided that I would spend some time learning about various technologies that I use or would like to use, and finding out more about them. In this week's installment, I'm taking a look at just, a command runner that is so good.
justfile
I've been using justfiles in my projects for a while now thanks to Jeff Triplett, but there's just so much to them. I read through the docs this week and found 19 things that look useful to incorporate into my just files.
1. default-list
When you run just in your terminal it will run the first recipe listed in your file. One way I had overcome this was by adding the following recipe:
@_default:
    just --list
This would cause just to list all of the commands available (with comments if they exist)
However, there's a different way to do this. You can add
set default-list := true
at the top of the justfile and get the same behavior.
2. Variadic parameters
One of the recipes I rely on frequently is
# Bring up Docker containers
[group('docker')]
@up *ARGS:
    docker compose -f docker-compose.dev.yml up {{ ARGS }}
The *ARGS is what's known as a variadic parameter. These can accept a (potentially) infinite number of parameters passed to them. You can either use + to indicate 1 or more parameters, or a * to indicate 0 or more parameters.
The recipe above allows the following invocations
# Bring the Docker container up in the foreground
just up
# Bring the Docker container up in detached mode
just up -d
# Build the Docker container and then bring the Docker container up in the detached mode
just up --build -d
The new thing I learned is that they can also accept defaults. This means that I could update the recipe to be
# Bring up Docker containers
[group('docker')]
@up *ARGS='-d':
    docker compose -f docker-compose.dev.yml up {{ ARGS }}
This would cause
just up
and
just up -d
to behave the same.
I could also just update the recipe to be
# Bring up Docker containers
[group('docker')]
@up *ARGS:
    docker compose -f docker-compose.dev.yml up -d {{ ARGS }}
I'm trying to figure out the best use case for this, but it did seem like an interesting concept to try out
3. Variadic parameters limits
You may want to limit the number of parameters you allow on a variadic parameter. Just allows you to control this by using [arg('ARGS', min='1', max='4')] like this
# Bring up Docker containers
[group('docker')]
[arg('ARGS', min='1', max='4')]
@up *ARGS:
    docker compose -f docker-compose.dev.yml up {{ ARGS }}
In order for this to work, you do need to add the following to your justfile
set unstable
set lists
Quick Aside ... The docs give a better example using
scpwhich likely makes more sense, but I wanted to keep the same example going here
4. Parameter constraints
You can constrain parameters using [arg('ARGS', pattern='--help|--version')].
Per the docs
Regular expressions are provided by the Rust regex crate. See the syntax documentation for usage examples.
We again can update the just recipe from before to be
# Bring up Docker containers
[group('docker')]
[arg('ARGS', pattern='-d|--build')]
@up *ARGS:
    docker compose -f docker-compose.dev.yml up {{ ARGS }}
Again, not helpful in this case necessarily, but there are applications with other recipes I'm sure
5. Usage information
Usage information for a recipe may be printed with the --usage subcommand. I have the following recipe that creates new posts for this site (please excuse the mix of make with just)
@post title category:
    make newpost title="{{title}}" category="{{category}}"
If I run just --usage post I get this returned
Usage: just post title category

Arguments:
  title
  category
This can be helpful when you aren't sure what the arguments are for a just recipe (if they exist at all!)
6. Run recipes at the end
You can have recipes run at the end of a recipe, not just the beginning. Typically when running a just recipe any dependencies will run before the invoked recipe.
For example, assume you have these recipes:
test: build
    run tests

build:
    build project
If you run just test it will first run the build recipe and then the test recipe.
Let's assume you also have a deployment recipe that you want to run AFTER the build recipe runs successfully. You could have the following justfile:
test: build && deploy
    run tests

build:
    build project

deploy:
    deploy project
Running the command just test would do the following
- Run the
buildrecipe - Run the
testrecipe - Run the
deployrecipe
See the docs for more examples
7. Parallel Tasks
You can run parallel tasks with the [parallel] invocation above a recipe. This could be helpful if you have a project with a front end and a back end and you want to run the tests at the same time:
[parallel]
test: fe be

fe:
    test front-end-project

be:
    test back-end-project
See the docs for more details
8. Recipe documentation
Who doesn't love good documentation, right? just allows for a few options for docs
- The
#symbol - The
[doc('Your Comment Here')]attribute
Why choose one over the other? The # only allows for single line documentation, while the [doc()] attribute allows for multi-line documentation.
One thing to note on multi-line documentation is that it can look a bit off
This just recipe
[group('docker')]
[doc('
Bring up Docker containers
A second line
and a third
')]
@up *ARGS:
    docker compose -f docker-compose.dev.yml up {{ ARGS }}
will generate this documentation
    # Bring up Docker containers
    # A second line
    # and a third
    up *ARGS
See the docs for more details
9. Groups
In the previous example there was [group('docker')]. This attribute allows you to group recipes together. For a really good example, see the Django Packages justfile
Running just will return
Available recipes:
    [database]
    pg_dump file='db.dump'           # Dump database to file
    pg_restore file='db.dump'        # Restore database from dump file

    [django]
    collectstatic *ARGS="--no-input" # Collect static files
    createsuperuser USERNAME EMAIL   # Create a Django superuser
    cron                             # Run scheduled data import tasks
    run ARGS                         # Run a Django management command
    shell *ARGS                      # Run Django shell

    [docker]
    build *ARGS                      # Builds the Docker Images with optional arguments
    cibuild                          # Build Docker images for CI
    console                          # Drop into a bash shell in the Django container
    down *ARGS                       # Bring down Docker containers
    logs *ARGS                       # View output from running containers
    remove                           # Remove all application services and volumes
    restart *ARGS                    # Restart all services
    start *ARGS="--detach"           # Start all services
    status                           # Show status of running containers
    stop                             # Stop all services
    tail                             # Tail service logs
    up *ARGS                         # Start Docker containers

    [docs]
    docs-build *ARGS                 # Build the documentation to docs/site
    docs-down *ARGS                  # Stop documentation services
    docs-up *ARGS="--detach"         # Start documentation services

    [linting]
    lint *ARGS                       # Run all prek linting and code quality checks
    perflint                         # Check for performance anti-patterns

    [production]
    purge_cache                      # Purge Cloudflare cache

    [testing]
    coverage *ARGS                   # Run tests with pytest and generate coverage reports
    pytest *ARGS                     # Run tests with pytest
    test *ARGS                       # Run tests using Django test runner

    [utils]
    bootstrap *ARGS                  # Perform initial setup: create venv, .env.local, and build Docker images
    bump *ARGS                       # Update the version; Used before release to production
    fmt                              # Format the justfile
    lock *ARGS                       # Compile Python dependencies with hashes [alias: pip-compile]
    setup                            # Alias for bootstrap - perform initial setup
    upgrade                          # Upgrade existing Python dependencies to their latest versions
You can list the groups by running just --groups. However, in order to list the recipes in a specific group you need to run just --list --group <group-name>, for example, just --list --group docker.
It would be nice if running just --group docker would work, but as of just 1.59.0 it generates an error
error: the following required arguments were not provided:
  --list [<MODULE>...]

Usage: just --list [<MODULE>...] --group <GROUP> [ARGUMENTS]...

For more information, try '--help'.
10. Private Recipes
There is a concept of private recipes by using the [private] attribute. The main use is helper recipes that exist only to be dependencies or building blocks.
For example, in the Django Packages justfile the recipe
# Format the justfile
[group('utils')]
@fmt:
    just --fmt --unstable
could be changed to
# Format the justfile
[private]
[group('utils')]
@fmt:
    just --fmt --unstable
This would cause the fmt recipe to not be listed when showing all of the recipes.
11. Shell expanded strings
Per the docs
Strings prefixed with
xare shell expanded (as of version 1.27.0)
One interesting thing that can be done here is that you can keep common recipes in one place and pull them into every project’s justfile like this:
import x'~/.config/just/common.just'
More on common justfiles a little later
12. Set your shell
You can set the shell that just will use. This can be especially helpful on Windows where you are running Powershell instead of WSL.
On Windows you can set it like this:
[windows]
set shell := ["powershell.exe", "-NoLogo", "-Command"]
This can make it much easier to have a single justfile that can be used on Windows, macOS, or Linux.
See more at the docs
13. Working Directory
You can set the working directory for an entire justfile or a single recipe. I'm still trying to figure out the best use case for this, but one thing that might be helpful is that if you have a sub-directory called scripts that has all of your scripts and you don't want to have every just recipe that invokes a script to look like this:
simple:
    ./scripts/simple.sh

complicated:
    ./scripts/complicated.sh
You could add set working-directory := 'scripts' like this
set working-directory := 'scripts'
simple:
    ./simple.sh

complicated:
    ./complicated.sh
Again, I'm still trying to figure out a good use case for this, but it was interesting enough to catch my eye
See docs for more details
14. Importing other justfiles
If you need/want to separate your various just recipes into separate files you can do that. Assume that you have a justfile and several sub-justfiles that look something like this:
.
├── be.just
├── fe.just
├── docker.just
└── justfile
The be.just might look like this:
[doc('Used to run the back end tests')]
[group('backend')]
@be-test:
    echo "run back end tests"

[doc('Used to run the back end build')]
[group('backend')]
@be-build: be-test
    echo "run back end build"
the fe.just might look like this
[doc('Used to run the front end tests')]
[group('frontend')]
@fe-test:
    echo "run front end tests"

[doc('Used to run the front end build')]
[group('frontend')]
@fe-build: fe-test
    echo "run front end build"
the docker.just might look like this:
[doc('Bring Docker Containers up')]
[group('docker')]
up *ARGS:
    docker compose up {{ARGS}}

[doc('Bring Docker Containers down')]
[group('docker')]
down:
    docker compose down
We can then have a justfile that looks like this:
import 'be.just'
import 'fe.just'
import 'docker.just'

set default-list := true
We can set whatever other settings in the justfile we want. This allows us to have a separation of concerns for our just recipes.
See the docs for more details. You can also pull shared recipes in from a common file — see tip 11.
15. set fallback
When you add set fallback you can traverse the directory up to a justfile with the recipe you're trying to find. For example, if you have a justfile in your home directory that looks like this:
@default:
    just --list

[no-cd]
pwd:
    pwd

[no-cd]
gist file:
    gh api gists -F 'files[{{ file }}][content]=@{{ file }}'

@usage time="daily":
    npx ccusage@latest {{ time }} --breakdown

[no-cd]
@gh profile:
    uvx gh-profiler {{ profile }}

@glm:
    uvx glm-launch launch claude
but you're in the directory ~/code/ryancheley.com that has a justfile that looks like this:
set default-list := true

@html:
    make html

@clean:
    make clean

@regenerate:
    make regenerate

@serve:
    pelican --listen --autoreload

@publish:
    make publish

@vercel: html
    rsync -av pelican.db metadata.json search.ryancheley@do-web-p-003:~

@toot:
    make toot

@post title category:
    make newpost title="{{title}}" category="{{category}}"

@micro title:
    make newpost title="{{title}}" category="microblog"

@sync:
    make sync

@lock:
    make lock

@check:
    pre-commit run --all-files

@codespell:
    codespell content -i 3 --ignore-words=ignore-words.txt

# Generate resume and cover letter PDFs from the Markdown in resume-resources/
@resume:
    #!/usr/bin/env bash
    set -euo pipefail
    cd resume-resources
    header=$(mktemp)
    printf '\\AtBeginDocument{\\raggedright}\n' > "$header"
    pandoc resume.md -o "Ryan Cheley Resume.pdf" --pdf-engine=xelatex -V geometry:margin=1in -V linkcolor:blue -H "$header"
    pandoc cover-letter.md -o "Ryan Cheley Cover Letter.pdf" --pdf-engine=xelatex -V geometry:margin=1in -V linkcolor:blue -H "$header"
    rm -f "$header"

# Bring up Docker containers
[group('docker')]
@up *ARGS:
    docker compose -f docker-compose.dev.yml up {{ ARGS }}

# Bring down Docker containers
[group('docker')]
@down *ARGS:
    docker compose down {{ ARGS }}


# Builds the Docker Images with optional arguments
[group('docker')]
@build *ARGS:
    docker compose {{ ARGS }} build
If you wanted to run the usage recipe you'd get an error like this:
error: justfile does not contain recipe `usage`
However, if you add set fallback to the top of the justfile in ~/code/ryancheley.com then the recipe will run without issue. For example:
set default-list := true
set fallback

@html:
    make html

...
See docs for more details
16. Remote justfile
Let's say you really like the Django Packages justfile and you wanted to include it in your justfile. You could add the following to the top of your just file
import? 'djangopackages.just'
set allow-duplicate-recipes
The first line optionally imports a file called djangopackages.just. The second line isn't strictly necessary, but in the event you have a recipe with the same name as one used in djangopackages.just this allows you to not get an error. One caveat is that the last version of the recipe is what will be used. In this example, since the import? 'djangopackages.just' appears at the top, the lock recipe will be the one from the justfile and not from djangopackages.just
You can then add this recipe to your justfile:
fetch:
    curl https://raw.githubusercontent.com/djangopackages/djangopackages/refs/heads/main/justfile > djangopackages.just
In order to have the djangopackages.just file you'll need to run the just fetch recipe.
17. The --choose flag
The --choose flag will list out recipes (with some exceptions) so you can select them; good for learning about the recipes available. In order to use this you'll need to install fzf. This can be installed with brew install fzf on macOS.
One caveat here is that it won't list out recipes that have arguments passed to them. Additionally private recipes (item 10) and aliases are skipped.
See the docs here.
18. Confirm attribute
Let's say you have a super destructive just recipe like this:
delete-all:
    rm -rf *
When you run just delete-all it will run the command without prompting. You can prevent that behavior by adding the [confirm] attribute to the recipe
[confirm]
delete-all:
    rm -rf *
So when you run just delete-all instead of nuking all of the files, you'll get prompted to confirm that decision
Run recipe `delete-all`?
N if you invoked the recipe by mistake.
See the docs for more details.
19. Format your justfile
A simple way to check that your justfile is formatted correctly is to run just --fmt --check
You can then run just --fmt to format it correctly.
See the docs for more details.
Migrating to Hetzner with Coolify
What I did
A few weeks ago, I got to watch Jeff Triplett migrate DjangoPackages from DigitalOcean to Hetzner1 using Coolify. The magical world of Coolify made everything look just so ... easy. Jeff mentioned that one of the driving forces for the decision to go to Hetzner was the price, that is Hetzner is cheaper but with the same quality.
Aside
To give some perspective, the table below shows a comparison of what you I had and what I pay(paid) at each VPS
| Server Spec | Digital Ocean Cost | Hetzner Cost | Count |
|---|---|---|---|
| Managed Database with 1GB RAM, 1vCPU | $15.15 | NA | 2 |
| s-1vcpu-2gb | $12 | NA | 1 |
| s-1vcpu-1gb | $6 | NA | 3 |
| cpx11 | NA | $4.99 | 2 |
| cpx21 | NA | $9.99 | 2 |
| cpx31 | NA | $17.99 | 1 |
With Digital Ocean I was paying about $72.50 per month for my servers. This got me 2 Managed Databases (@$15 each) and 4 Ubuntu servers (1 s-1vcpu-2gb and 3 s-1vcpu-1gb).
Based on my maths for January I should see my Hetzner bill be about $61 with the only downside being that I have to 'manage' my databases myself ... however, with Digital Ocean I always felt like I was playing with house money because I didn't have the paid for backups. Now, with Hetzner, I have backups saved to an S3 bucket (and Coolify has amazing docs for how to set this up!)
End Aside
Original State
I had 6 servers on Digital Ocean
- 3 production web servers
- 1 test web server
- 1 managed database production server
- 1 managed database test server
This cost me roughly $75 per month.
Current State
- 2 production web servers
- 1 test web server
- 1 production database server
- 1 test database server
This cost me roughly $63 per month.
Setting Up Hetzner
In order to get this all started I need to create a Hetzner account2. Once I did that I created my first server, a CPX11 so that I could install Coolify.
Next, I need to clean up my DNS records. Over the years I had DNS managed at my registrar of choice (hover.com) and within Digital Ocean. Hetzner has a DNS server, so I decided to move everything there. Once all of my DNS was there, I added a record for my Coolify instance and proceeded with the initial set up.
In all I migrated 9 sites. They can be roughly broken down like this
Coolify: setting up projects, environments, resources
Coolify has several concepts that took a second to click for me
It took me some time reading through the docs but once it clicked I ended up segregating my projects in a way that made sense to me. I also ended up creating 2 environments for each project:
- Production
- UAT
Starting with Nixpacks
Initially I thought that Coolify would only support Docker or docker-compose files, but there is also an option for static sites, and Nixpacks. It turns out that Nixpacks were exactly what I wanted in order to get started.
NB: There is a note on the Nixpacks site that states
"⚠️ Maintenance Mode: This project is currently in maintenance mode and is not under active development. We recommend using Railpack as a replacement."
However, Railpack isn't something that Coolify offered so 🤷🏻♂️
I have a silly Django app called DoesTatisJrHaveAnErrorToday.com3 that seemed like the lowest risk site to start with on this experiment.
Outline of Migration steps
- Allow access to database server from associated Hetzner server, i.e. Production Hetzner server needs to access Production Digital Ocean managed database server, UAT Hetzner Web server needs access to UAT Digital Ocean managed database server
- Set up hetzner.domain.tld in DNS record, for example, hetzner.uat.doestatisjrhaveanerrortoday.com
- Set up site in Coolify in my chosen Project, Environment, and Resource. For me this was Tatis, UAT, "Does Tatis Jr Have An Error UAT"
- Configure the General tab in Coolify. For me this meant just adding an entry to 'Domains' with
https://hetzner.uat.doestatisjrhaveanerrortoday.com - Configure environment variables 4. 5
- Hit Deploy
- Verify everything works
- Update the
General>Domainsentry to havehttps://hetzner.uat.doestatisjrhaveanerrortoday.comandhttps://uat.doestatisjrhaveanerrortoday.com - Update DNS to have UAT point to Hetzner server
- Deploy again
- Wait ... for DNS propagation
- Verify
https://uat.doestatisjrhaveanerrortoday.comworks - Remove
https://hetzner.uat.doestatisjrhaveanerrortoday.comfrom DNS and Coolify - Deploy again
- Verify
https://uat.doestatisjrhaveanerrortoday.comstill works - Remove the GitHub Action I had to deploy to my Digital Ocean UAT server
- Repeat for Production, replacing
https://hetzner.uat.doestatisjrhaveanerrortoday.comwithhttps://hetzner.doestatisjrhaveanerrortoday.com
Repeat the process for each of my other Django sites (all 4 of them)
Switching to Dockerfile/docker-compose.yaml
This worked great, but
- The highest version of Python with Nixpacks is Python 3.13
- The warning message I mentioned above about Nixpacks being in "Maintenance Mode"
Also, I had a Datasette / Django app combination that I wanted to deploy, but couldn't figure out how with NIXPACKS. While the Django App isn't where I want it to be, and I'm pretty sure there's a Datasette plugin that would do most of what the Django app does, I liked the way it was set up and wanted to keep it!
Writing the Dockerfile and docker-compose.yaml files
I utilized Claude to assist with starting me off on my Dockerfile and docker-compose.yaml files. This made migrating off of the NIXPACK a bit easier than I thought it would be.
I was able to get all of my Django and Datasette apps onto a Dockerfile configuration but there was one site I have that scrape game data from TheAHL.com which has an accompanying Django app that required a docker-compose.yaml file to get set up6.
One gotcha I discovered was that the Coolify UI seems to indicate that you can declare your docker-compose file with any name, but my experience was that it expected the file to be called docker-compose.yaml not docker-compose.yml which did lead to a bit more time troubleshooting that I would have liked!
Upgrading all the things
OK, now with everything running from Docker I set about upgrading all of my Python versions to Python 3.14. This proved to be relatively easy for the Django apps, and a bit more complicated with the Datasette apps, but only because of a decision I had made at some point to pin to an alpha version 1.0 of Datasette. Once I discovered the underlying issue and resolved it, again, a walk in the park to upgrade.
Once I was on Python 3.14 it was another relatively straight forward task to upgrade all of my apps to Django 6.0. Honestly, Docker just feels like magic given what I was doing before and just how worried I'd get when trying to upgrade my Python versions or my Django versions.
Migrating database servers
Now I've been able to wind down all of my Web Servers, the only thing left is my managed database servers. In order to get them set up I set up pgadmin (with the help of Coolify) so that I didn't have to drop into psql in the terminal on the servers I was going to use for my database servers.
Once that was done I created backups of each database from Production and UAT on my MacBook so that I could restore them to the new Hetzner servers. To get the backup I ran this
docker run --rm postgres:17 pg_dump "postgresql://doadmin:password@host:port/database?sslmode=require" -F c --no-owner --no-privileges > database.dump
I did this for each of my 4 databases. Why did I use the docker run --rm postgres:17 pg_dump instead of just pg_dump? Because my MacBook had Postgres 16 while the server was on Postgres 17 and this was easier than upgrading my local Postgres instance.
Starting with UAT
I started with my test servers first so I could break things and have it not matter. I used my least risky site (tatis) first.
The steps I used were:
- Create database on Hetzner UAT database server
- Restore from UAT on Digital Ocean
- Repeat for each database
- Open up access to Hetzner database server for Hetzner UAT web server
- Change connection string for
DATABASE_URLfor tatis to point to Hetzner server in my environment variables - Deploy UAT site
- Verify change works
- Drop database from UAT Digital Ocean database server
- Verify site still runs
- Repeat for each Django app on UAT
- Allow access to Digital Ocean server from only my IP address
- Verify everything still works
- Destroy UAT managed database server
- Repeat for prod
For the 8 sites / databases this took about 1 hour. Which, given how much needed to be done was a pretty quick turn around. That being said, I spent probably 2.5 hours planning it out to make sure that I had everything set up and didn't break anything, even on my test servers.
Backups
One thing about the Digital Ocean managed servers is that backups were an extra fee. I did not pay for the backups. This was a mistake ... I should have, and it always freaked me out that I didn't have them enabled. Even though these are essentially hobby projects, when you don't do the right thing you know it.
Now that I'm on non-managed servers I decided to fix that, and it turns out that Coolify has a really great tutorial on how to set up an AWS S3 bucket to have your database backups written to.
It was so easy I was able to set up the backups for each of my databases with no fuss.
Coolify dashboard thing
I mentioned above that I upgraded all of apps to Python 3.14 and Django versions to 6.0. For all of the great things about Coolify, trying to find this information out on a high level is a pain in the ass. Luckily they have a fairly robust API that allowed me to vibe code a script that would output an HTML file that showed me everything I needed to know about my Applications with respect to Python, Django, and Datasette versions. It also helped me know about my database backup setups as well7!
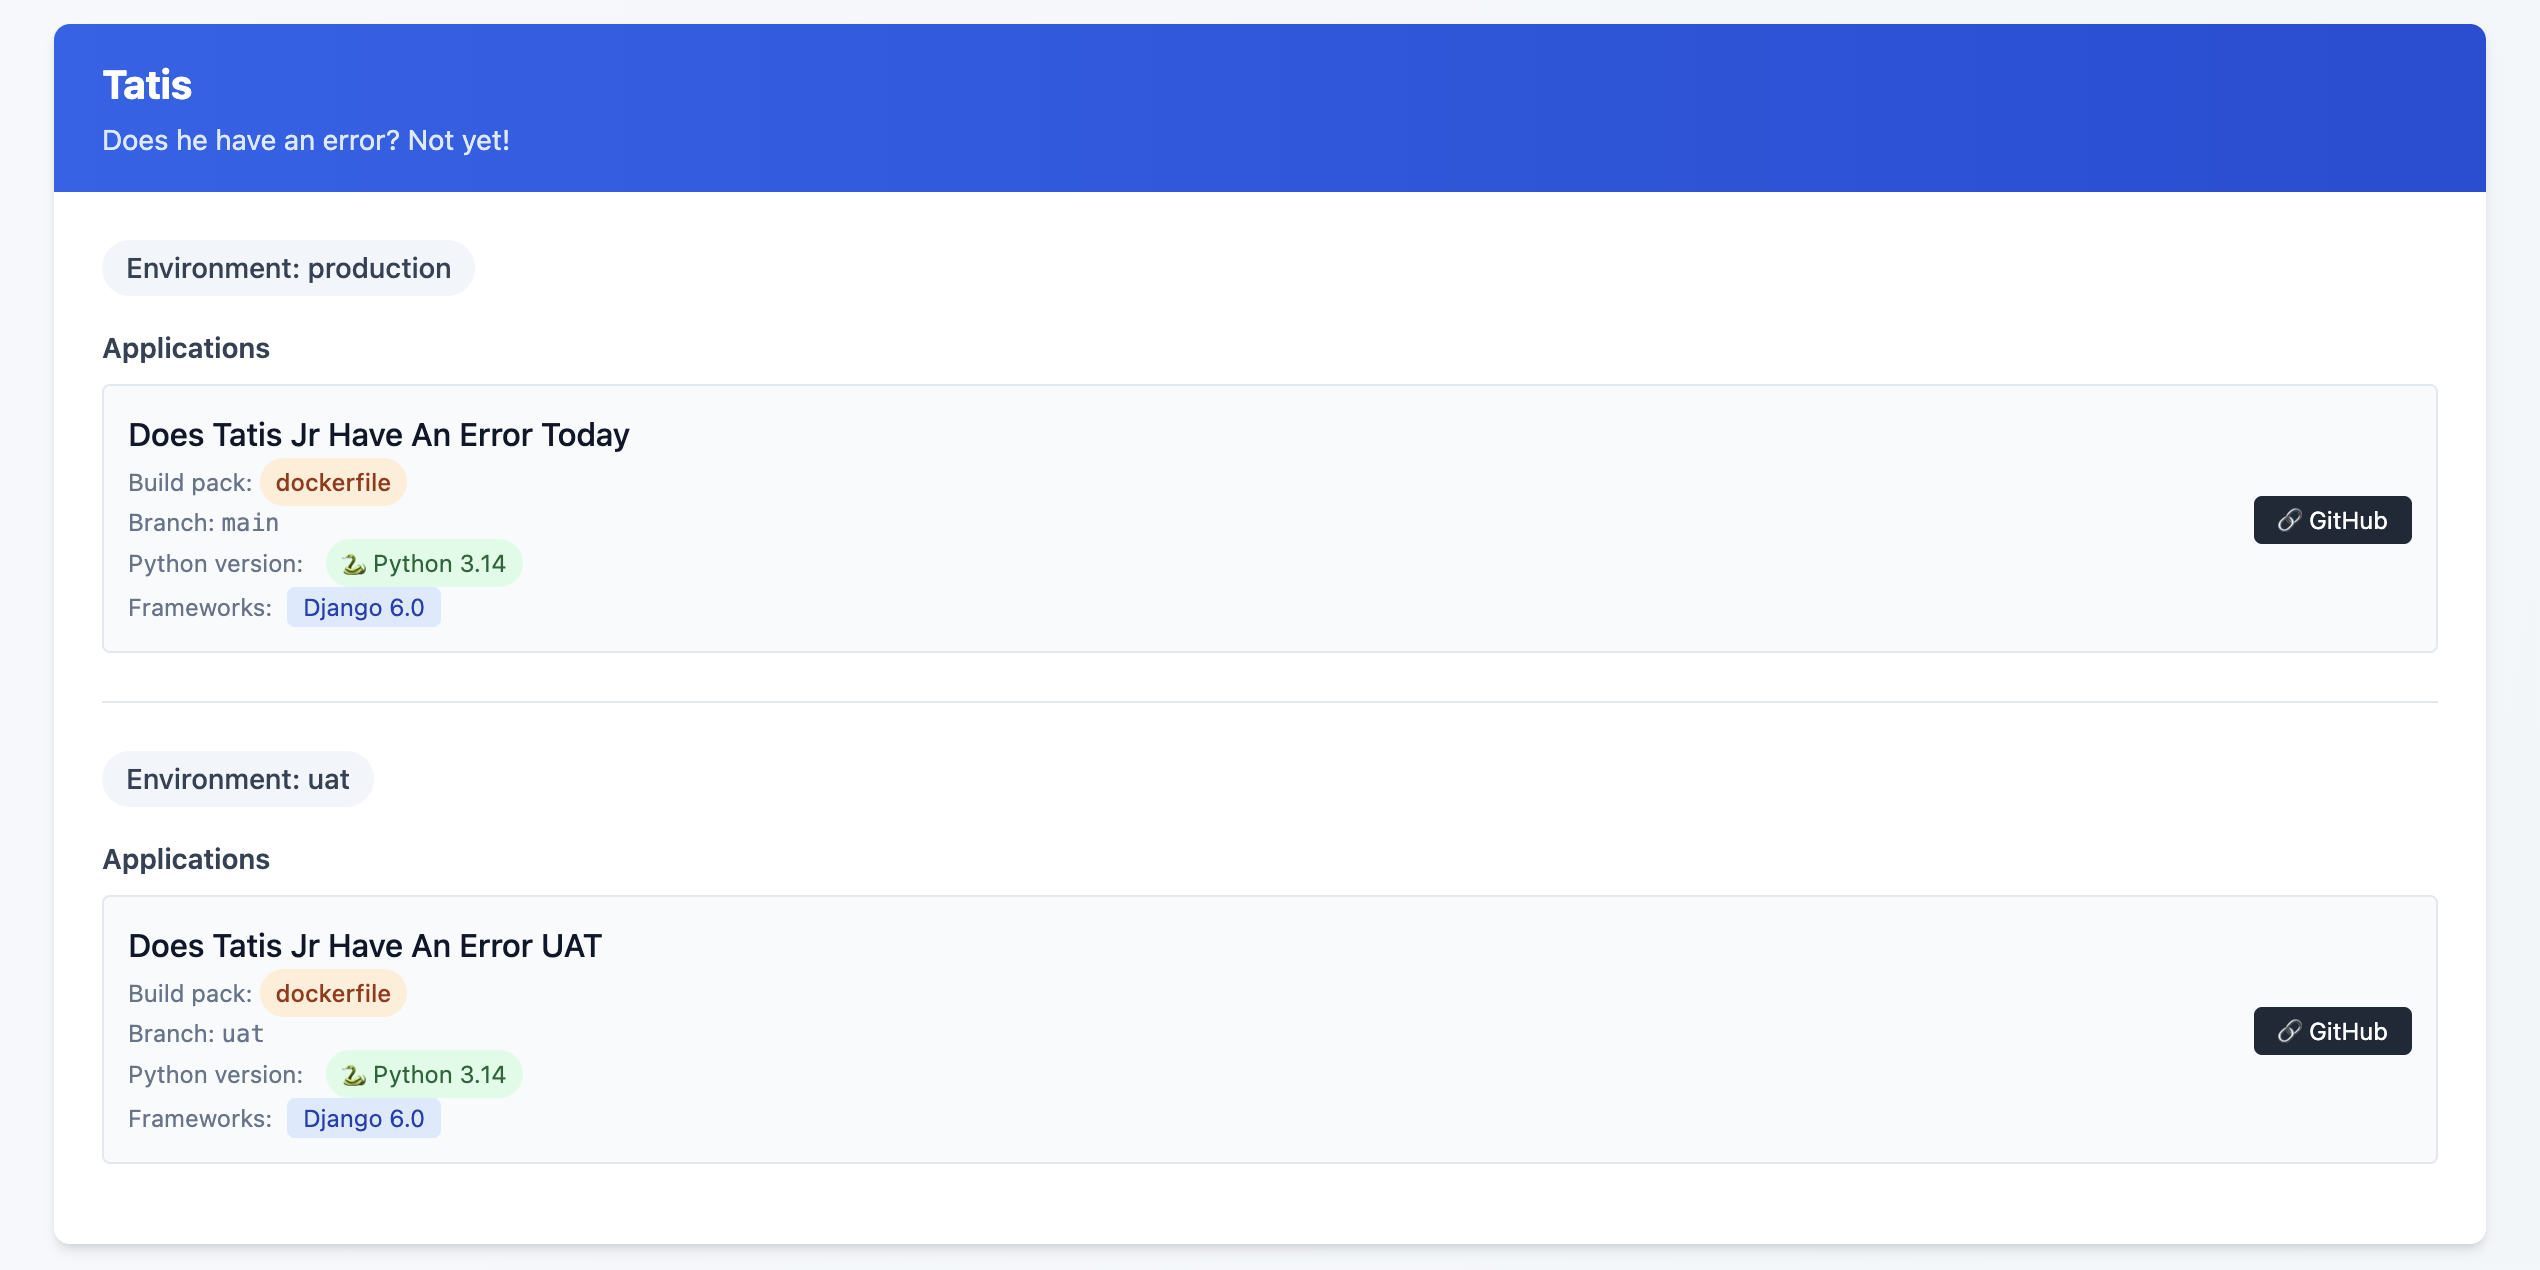
This is an example of the final state, but what I saw was some Sites on Django 4.2, others on Python 3.10 and ... yeah, it was a mess!
I might release this as a package or something at some point, but I'm not sure that anyone other than me would want to use it so, 🤷♂️
What this allows me to do now
One of the great features of Coolify are Preview Deployments which I've been able to implement relatively easily8. This allows me to be pretty confident that what I've done will work out OK. Even with a UAT server, sometimes just having that extra bit of security feels ... nice.
One thing I did (because I could, not because I needed to!) was to have a PR specific database on my UAT database server. Each database is called {project}_pr and is a full copy of my UAT database server. I have a cron job set up that restores these databases each night.
I used Claude to help generate the shell script below:
#!/bin/bash

# Usage: ./copy_db.sh source_db container_id [target_db]
# If target_db is not provided, it will be source_db_pr

source_db="$1"
container_id="$2"
target_db="$3"

# Validate required parameters
if [ -z "$source_db" ]; then
    echo "Error: Source database name required"
    echo "Usage: $0 source_db container_id [target_db]"
    exit 1
fi

if [ -z "$container_id" ]; then
    echo "Error: Container ID required"
    echo "Usage: $0 source_db container_id [target_db]"
    exit 1
fi

# Set default target_db if not provided
if [ -z "$target_db" ]; then
    target_db="${source_db}_pr"
fi

# Dynamic log filename
log_file="${source_db}_copy.log"

# Function to log with timestamp
log_message() {
    echo "$(date '+%Y-%m-%d %H:%M:%S') - $*" | tee -a "$log_file"
}

log_message "Starting database copy: $source_db -> $target_db"
log_message "Container: $container_id"

# Drop existing target database
log_message "Dropping database $target_db if it exists..."
if docker exec "$container_id" psql -U postgres -c "DROP DATABASE IF EXISTS $target_db;" >> "$log_file" 2>&1; then
    log_message "✓ Successfully dropped $target_db"
else
    log_message "✗ Failed to drop $target_db"
    exit 1
fi

# Create new target database
log_message "Creating database $target_db..."
if docker exec "$container_id" psql -U postgres -c "CREATE DATABASE $target_db;" >> "$log_file" 2>&1; then
    log_message "✓ Successfully created $target_db"
else
    log_message "✗ Failed to create $target_db"
    exit 1
fi

# Copy database using pg_dump
log_message "Copying data from $source_db to $target_db..."
if docker exec "$container_id" sh -c "pg_dump -U postgres $source_db | psql -U postgres $target_db" >> "$log_file" 2>&1; then
    log_message "✓ Successfully copied database"
else
    log_message "✗ Failed to copy database"
    exit 1
fi

log_message "Database copy completed successfully"
log_message "Log file: $log_file"
Again, is this strictly necessary? Not really. Did I do it anyway just because? Yes!
Was it worth it
Hell yes!
It took time. I'd estimate about 3 hours per Django site, and 1.5 hours per non-Django site. I'm happy with my backup strategy, and preview deployments are just so cool. I did this mostly over the Christmas / New Year holiday as I fought through a cold.
Another benefit of being on Coolify is that I'm able to run
What's next?
Getting everything set up to be mostly consistent is great, but there are still some differences that exist between each Django site that don't need to when it comes to the Dockerfile that each site is using.
I also see the potential to have better alignment on the use of my third party packages. Sometimes I chose package X because that's what I knew about at the time, and then I discovered package Y but never went back and switched it out where I was using package X before.
Finally, I really want to figure out the issue of https on some of the preview deployments.
- This is an affiliate link ↩︎
- This is an affiliate link ↩︎
- More details on why I have this site here ↩︎
- Considerations for Nixpacks. The default version of Python for Nixpacks is 3.11. You can override this with an environment variable
NIXPACKS_PYTHON_VERSIONto allow up to Python 3.13. ↩︎ - Here, you need to make sure that your ALLOWED_HOSTS is
hetzner.uat.doestatisjrhaveanerrortoday.com↩︎ - Do I need this set up? Probably not. I'm pretty sure there's a Datasette plugin that does allow for edits in the SQLite database, but this was more of a Can I do this, not I need to do this kind of thing ↩︎
- There are a few missing endpoints, specifically when it comes to Service database details ↩︎
- one of my sites doesn't like serving up the deployment preview with SSL, but I'm working on that! ↩︎
Details on My Candidate Statement for the DSF
The Django Software Foundation Board of Directors elections are scheduled for November 2025 and I’ve decided to throw my hat into the ring. My hope specifically, if elected, is to be selected as the Treasurer. I have 4 main objectives over my two year term.
- Getting an Executive Director (ED) to help run the day-to-day operations of the DSF
- Identifying small to midsized companies for sponsorships
- Implementing a formal strategic planning process
- Setting up a fiscal sponsorship program to allow support of initiatives like Django Commons
These are outlined in my candidate statement, but I want to provide a bit more detail why I think they’re important, and some high level details on a plan to get them to completion.
These four goals are interconnected. We need an ED to scale operations, but funding an ED requires increased revenue through corporate sponsorships. Both benefit from having a strategic plan that guides priorities. And fiscal sponsorship potentially creates a new revenue stream while strengthening the ecosystem. This isn't four separate initiatives - it's a coherent plan for sustainable growth.
Getting an Executive Director (ED) to help run the day-to-day operations of the DSF
An ED provides day-to-day operational capacity that volunteer boards simply cannot match. While board members juggle DSF work with full-time jobs, an ED could:
- Call potential corporate sponsors every week, not just when someone has spare time
- Coordinate directly with Django Fellows on priorities and deliverables
- Support DjangoCon organizers across North & South America, Europe, Africa, and Asia with logistics and continuity
- Respond to the steady stream of trademark, licensing, and community inquiries
- Write grant applications to foundations that fund open source
- Prepare board materials so directors can focus on governance, not research
As Jacob Kaplan-Moss says in his 2024 DjangoCon US talk
We’re already at the limit of what a volunteer board can accomplish
Right now we're missing opportunities because volunteer bandwidth is maxed out. We can't pursue major corporate sponsors that need regular touchpoints. We can't support ecosystem projects that need fiscal sponsorship. We can't scale the Fellows program even though there's clearly more work than the current Fellows can handle.
As Treasurer, hiring an ED would be my top priority. Based on comparable nonprofit ED salaries, a part-time ED (20 hours/week) would cost approximately $60,000-$75,000 annually including benefits and overhead. A full-time ED would be $120,000-$150,000.
The DSF's current annual budget is roughly $300,000. Adding even a part-time ED would require increasing revenue by 25-30%. This is exactly why my second priority focuses on corporate sponsorships - we need sustainable revenue growth to support professional operations.
The path forward is phased: board members initiate corporate outreach to fund a part-time ED, who then scales up fundraising efforts to eventually become full-time and bring us toward that $1M budget Jacob outlined. We bootstrap professional operations through volunteer effort, then let the professional accelerate what volunteers started.
Identifying small to midsized companies for sponsorships
In Jacob Kaplan-Moss' 2024 DjangoCon US Talk, he outlines what the DSF could do with a $1M budget. I believe this is achievable, but it requires a systematic approach to corporate sponsorships.
Currently, the DSF focuses primarily on major sponsors. This makes sense - volunteer boards have limited bandwidth, so targeting "whales" is efficient. But we're leaving significant revenue on the table.
Consider the numbers: US Census data shows roughly 80,000-400,000 small to mid-sized tech companies (depending on definitions). Stack Overflow's 2024 survey indicates 46.9% of professional developers use Python, and 38% of Python web developers use Django. Even capturing a small fraction of companies using Django in production at a modest sponsorship tier ($500-$2,500/year) could significantly increase DSF revenue.
The challenge isn't identifying companies - it's having capacity to reach them. This is where an Executive Director becomes critical.
What an Executive Director Would Enable
A part-time Executive Director (ED) could:
- Dedicate 10+ hours weekly to corporate outreach instead of the 1-2 hours volunteer board members can spare
- Maintain a CRM system tracking sponsor relationships, touchpoints, and renewal cycles
- Create targeted outreach campaigns to Django-using companies in specific sectors (healthcare tech, fintech, e-commerce, etc.)
- Develop case studies showing Django's business value to help companies justify sponsorship
- Provide consistent follow-up and relationship management that volunteer boards cannot maintain
My First 90 Days as Treasurer
If elected, here's my concrete plan:
Month 1:
- Audit current sponsors and revenue sources
- Identify 20 target companies (mix of sizes) currently using Django
- Work with current board to draft outreach templates and sponsorship value propositions
Month 2:
- Begin systematic outreach to target companies
- Track response rates and refine approach
- Engage with Django community leaders to identify additional prospects
Month 3:
- Report results to board
- If we've secured commitments for additional $30K-$50K in annual recurring revenue, propose budget to hire part-time ED
- Continue to push forward the ED recruitment process
This is realistic volunteer-level effort (5-8 hours/week) that proves the concept before committing to an ED hire. Once we have an ED, they can scale this 5-10x.
Implementing a formal strategic planning process
The DSF needs a strategic plan - not as a bureaucratic exercise, but as a practical tool for making decisions and measuring progress.
Right now, we operate somewhat reactively. The Fellows program exists because it was created years ago. DjangoCons happen because organizers step up. Corporate sponsorships come in when companies reach out to us. This isn't necessarily bad, but it means we're not proactively asking: What should Django's ecosystem look like in 5 years? How do we get there?
A strategic plan would give us:
Clear priorities: When opportunities arise (a major donor, a new initiative, a partnership proposal), we can evaluate them against stated goals rather than deciding ad-hoc.
Accountability: We can measure whether we're making progress on what we said mattered. Did we grow the Fellows program like we planned? Did sponsorship revenue increase as projected?
Communication: Community members and potential sponsors can understand where the DSF is headed and how they can contribute.
As someone who's been in healthcare management since 2012, I've seen how strategic planning drives organizational effectiveness. The best plans aren't 50-page documents that sit on a shelf - they're living documents that inform quarterly board discussions and annual budget decisions.
For the DSF, I envision a strategic planning process that:
Year 1:
- Conduct stakeholder interviews with Fellows, corporate sponsors, community leaders, and DjangoCon organizers
- Identify 3-5 strategic priorities for the next 3 years (e.g., "double sponsorship revenue," "launch fiscal sponsorship program," "expand geographic diversity of Django community")
- Develop measurable outcomes for each priority
- Share draft plan with community for feedback
Ongoing:
- Review progress quarterly at board meetings
- Publish annual progress reports
- Revise plan every 3 years based on outcomes and changing needs
This connects directly to my other goals: we need a strategic plan to guide ED hiring, fundraising priorities, and fiscal sponsorship criteria. Without it, we're making isolated decisions rather than building toward a coherent vision.
Setting up a fiscal sponsorship program to allow support of initiatives like Django Commons
Django's success isn't just about the framework itself. It's about the ecosystem of packages, tools, and community organizations that have grown around it. Projects like Django Commons, Django Packages, regional Django user groups, and specialized packages serve thousands of developers daily. Yet these projects face a common challenge: they lack the legal and financial infrastructure to accept donations, pay for infrastructure, or compensate maintainers.
A fiscal sponsorship program would allow the DSF to serve as the legal and financial home for vetted Django ecosystem projects. Think of it as the DSF saying: "We'll handle the paperwork, taxes, and compliance; you focus on serving the community."
Who This Helps
- Community maintainers who need to accept donations but shouldn't have to become nonprofit experts
- Django Commons and similar initiatives that need to pay for infrastructure, security audits, or maintainer stipends
- Regional Django organizations that want to organize events or workshops but lack financial infrastructure
- Critical packages in the Django ecosystem that need sustainable funding models
- Corporate sponsors who want to support the broader ecosystem but need a tax-deductible vehicle
Why This Matters
Right now, valuable Django ecosystem projects are essentially flying without a net. If Django Commons needs to accept a $10,000 corporate donation to fund security audits, there's no clear path to doing so. If a critical package needs to pay for CI/CD infrastructure or compensate a maintainer for urgent security fixes, they're stuck. Some projects, such as Djangonaut Space, have tried to solve this individually by creating their own 501(c)(3)s or using platforms like Open Collective, but this fragments the community and creates overhead.
The Python Software Foundation already does this successfully for PyPI, PyLadies, and regional Python conferences. NumFOCUS sponsors dozens of scientific Python projects. There's no reason Django's ecosystem shouldn't have similar support.
For the DSF, this is also about long-term sustainability. A healthy Django depends on a healthy ecosystem. When popular packages go unmaintained or community initiatives shut down due to funding constraints, Django suffers. By providing fiscal sponsorship, we strengthen the entire Django community while also creating a new (modest) revenue stream through administrative fees that can fund DSF operations.
Moving Forward Together
These four initiatives - (1) hiring an Executive Director, (2) growing corporate sponsorships, (3) implementing strategic planning, and (4) launching fiscal sponsorship - represent an ambitious but achievable vision for the DSF's next two years. They're not just ideas; they're a roadmap for taking Django from a volunteer-run project to a professionally-supported ecosystem that can serve millions of developers for decades to come.
If you believe in this vision and think I can help make it happen, I'd be honored to have your vote. You can find more about my background and community involvement in my candidate statement.
Thank you for taking the time to read this, and regardless of the election outcome, I'm committed to supporting Django's continued success.
Deploying n8n on Digital Ocean
This guide shows you how to deploy n8n, a workflow automation tool, on your own VPS. Self-hosting gives you full control over your data, avoids monthly subscription costs, and lets you run unlimited workflows without usage limits.
I'm using Digital Ocean1 for this guide, but these steps work on any VPS provider. You'll need:
- A VPS with Ubuntu 24.04 (minimum 1GB RAM)
- A domain name with DNS access
- Basic familiarity with SSH and command line tools
Create and configure the VPS
Create a droplet with Ubuntu 24.04. Select a plan with at least:
- 1GB RAM
- 25GB Disk
- 1 vCPU
Note the IP address - you'll need it for DNS configuration.
SSH into the server:
ssh root@ipaddress
Update the system:
apt update
apt upgrade -y
Install Docker
Install Docker using the official repository:
# Add Docker's official GPG key
sudo apt-get update
sudo apt-get install ca-certificates curl
sudo install -m 0755 -d /etc/apt/keyrings
sudo curl -fsSL https://download.docker.com/linux/ubuntu/gpg -o /etc/apt/keyrings/docker.asc
sudo chmod a+r /etc/apt/keyrings/docker.asc

# Add the repository to Apt sources
echo \
  "deb [arch=$(dpkg --print-architecture) signed-by=/etc/apt/keyrings/docker.asc] https://download.docker.com/linux/ubuntu \
  $(. /etc/os-release && echo "${UBUNTU_CODENAME:-$VERSION_CODENAME}") stable" | \
  sudo tee /etc/apt/sources.list.d/docker.list > /dev/null
sudo apt-get update

# Install Docker and its components
sudo apt-get install docker-ce docker-ce-cli containerd.io docker-buildx-plugin docker-compose-plugin
Configure DNS
Create an A record at your domain registrar pointing your subdomain (e.g., n8n.yourdomain.com) to your droplet's IP address. If you're using Hover, follow their DNS management guide.
Create Docker Compose configuration
Create a docker-compose.yml file on your server. Start with the Caddy service for handling SSL and reverse proxy:
services:
  caddy:
    image: caddy:latest
    ports:
      - "80:80"
      - "443:443"
    restart: always
    volumes:
      - ./Caddyfile:/etc/caddy/Caddyfile:ro
      - caddy_data:/data
      - caddy_config:/config
      - ./logs:/var/log/caddy
    deploy:
      resources:
        limits:
          cpus: '0.5'
          memory: 500M
    healthcheck:
      test: ["CMD", "caddy", "version"]
      interval: 30s
      timeout: 10s
      retries: 3
    logging:
      driver: "json-file"
      options:
        max-size: "10m"
        max-file: "3"
volumes:
  caddy_data:
  caddy_config:
Create a Caddyfile in the same directory, replacing n8n.mydomain.com with your actual domain:
n8n.mydomain.com {
    # Enable compression
    encode gzip zstd

    # Reverse proxy to n8n
    reverse_proxy n8n:5678 {
        header_up Host {host}
        header_up X-Real-IP {remote}
        header_up X-Forwarded-For {remote}
        header_up X-Forwarded-Proto {scheme}
        header_up X-Forwarded-Host {host}

        transport http {
            keepalive 30s
            keepalive_idle_conns 10
        }
        flush_interval -1
    }

    # Security headers (relaxed CSP for n8n's dynamic interface)
    header {
        Strict-Transport-Security "max-age=31536000; includeSubDomains; preload"
        X-Content-Type-Options "nosniff"
        X-Frame-Options "SAMEORIGIN"
        Referrer-Policy "strict-origin-when-cross-origin"
        Content-Security-Policy "default-src 'self'; script-src 'self' 'unsafe-inline' 'unsafe-eval'; style-src 'self' 'unsafe-inline'; img-src 'self' data: blob:; connect-src 'self' wss: ws:; frame-src 'self'; worker-src 'self' blob:;"
        -Server
    }

    # Enable logging
    log {
        output file /var/log/caddy/n8n-access.log {
            roll_size 10MB
            roll_keep 5
        }
        format json
    }

    # Enable TLS with reasonable settings
    tls {
        protocols tls1.2 tls1.3
    }
}
Add n8n to Docker Compose
Add the n8n service under services: in your docker-compose.yml file. Replace n8n.mydomain.com with your domain in the environment variables:
  n8n:
    image: n8nio/n8n:latest
    container_name: n8n
    restart: always
    environment:
      - N8N_HOST=n8n.mydomain.com
      - N8N_PORT=5678
      - WEBHOOK_URL=https://n8n.mydomain.com/
      - GENERIC_TIMEZONE=UTC
    ports:
      - "5678:5678"
    volumes:
      - n8n_data:/home/node/.n8n
      - /etc/timezone:/etc/timezone:ro
      - /etc/localtime:/etc/localtime:ro
    deploy:
      resources:
        limits:
          cpus: '1.0'
          memory: 1G
    healthcheck:
      test: ["CMD", "wget", "--no-verbose", "--tries=1", "--spider", "http://localhost:5678/healthz"]
      interval: 30s
      timeout: 10s
      retries: 3
      start_period: 60s
    logging:
      driver: "json-file"
      options:
        max-size: "10m"
        max-file: "3"
Add n8n_data: to the volumes: section in your docker-compose.yml file:
volumes:
  caddy_data:
  caddy_config:
  n8n_data: # new line
Your final docker-compose.yml file will look like this:
services:
  caddy:
    image: caddy:latest
    ports:
      - "80:80"
      - "443:443"
    restart: always
    volumes:
      - ./Caddyfile:/etc/caddy/Caddyfile:ro
      - caddy_data:/data
      - caddy_config:/config
      - ./logs:/var/log/caddy
    deploy:
      resources:
        limits:
          cpus: '0.5'
          memory: 500M
    healthcheck:
      test: ["CMD", "caddy", "version"]
      interval: 30s
      timeout: 10s
      retries: 3
    logging:
      driver: "json-file"
      options:
        max-size: "10m"
        max-file: "3"
  n8n:
    image: n8nio/n8n:latest
    container_name: n8n
    restart: always
    environment:
      - N8N_HOST=n8n.mydomain.com
      - N8N_PORT=5678
      - WEBHOOK_URL=https://n8n.mydomain.com/
      - GENERIC_TIMEZONE=UTC
    ports:
      - "5678:5678"
    volumes:
      - n8n_data:/home/node/.n8n
      - /etc/timezone:/etc/timezone:ro
      - /etc/localtime:/etc/localtime:ro
    deploy:
      resources:
        limits:
          cpus: '1.0'
          memory: 1G
    healthcheck:
      test: ["CMD", "wget", "--no-verbose", "--tries=1", "--spider", "http://localhost:5678/healthz"]
      interval: 30s
      timeout: 10s
      retries: 3
      start_period: 60s
    logging:
      driver: "json-file"
      options:
        max-size: "10m"
        max-file: "3"
volumes:
  caddy_data:
  caddy_config:
  n8n_data:
Start the containers
Run the containers in detached mode:
docker compose up -d
Complete the setup
Navigate to https://n8n.yourdomain.com in your browser. Follow the setup wizard to create your admin account. Once complete, you can start building workflows.
- Referral Link ↩︎
Why We Need to Stop Fighting About AI Tools and Start Teaching Them
In mid-June, Hynek tooted on Mastodon the following toot:
Watching the frustratingly fruitless fights over the USEFULNESS of LLM-based coding helpers, I've come down to 3 points that explain why ppl seem to live in different realities:
Most programmers:
1) Write inconsequential remixes of trivial code that has been written many times before.
2) Lack the taste for good design & suck at code review in general (yours truly included).
3) Lack the judgement to differentiate between 1) & FOSS repos of nontrivial code, leading to PR slop avalanche.
1/3
So, if you're writing novel code & not another CRUD app or API wrapper, all you can see is LLMs fall on their faces.
Same goes for bigger applications if you care about design. Deceivingly, if you lack 2), you won't notice that an architecture is crap b/c it doesn't look worse than your usual stuff.
That means that the era of six figures for CRUD apps is coming to an end, but it also means that Claude Code et al can be very useful for certain tasks. Not every task involves splitting atoms. 2/3
2/3
There's also a bit of a corollary here. Given that LLMs are stochastic parrots, the inputs determine the outputs.
And, without naming names, certain communities are more… rigorous… at software design than others.
It follows that the quality of LLM-generated code will inevitably become a decision factor for choosing frameworks and languages and I'm not sure if I'm ready for that.
3/3
I've been having a lot of success with using Claude Code recently so I've been thinking about this toot a lot lately. Simon Willison talks a lot about the things that he's been able to do because he just asks OpenAI's ChatGPT while walking his dog. He's asking a coding agent to help him with ideas he has in languages with which he may not be familiar. However, he's a good enough programmer that he can spot anti-patterns that are being written by the agent.
For me, it comes down to the helpfulness of these agentic coding tools; they can help me write boiler plate code more quickly. What it's really coming down to, for me, is that when something is trivially easy to implement, like another CRUD app or an API wrapper, those problems are solved. We don't need to keep solving them in ways that don't really help. What we need to do in order to be better programmers is figure out how to solve problems most effectively. And if that's creating a CRUD app or an API wrapper or whatever, then yeah, you're not solving any huge problem there. But if you're looking to solve something in a very unique or novel way, agentic coding tools aren't going to help you as much.
I don't need to know how the internal combustion engine of my car works. I do need to know that when the check engine light comes on, I need to take it to a mechanic. And then that mechanic is going to use some device that lets them know what is wrong with the car and what needs to be done to fix it. This seems very analogous to the coding agents that we're seeing now. We don't have to keep trying to solve those problems with well-known solutions. We can and we should rely on the knowledge that is available to us and use that knowledge to solve these problems quickly. This allows us to focus on trying to solve new problems that no one has ever seen.
This doesn't mean we can skip learning the fundamentals. Like blocking and tackling in football, if you can't handle the basic building blocks of programming, you're not going to succeed with complex projects. That foundational understanding remains essential.
The real value of large language models and coding agents lies in how they can accelerate that learning process. Being able to ask an LLM about how a specific GitHub action works, or why you'd want to use a particular pattern, creates opportunities to understand concepts more quickly. These tools won't solve novel problems for you—that's still the core work of being a software developer. But they can eliminate the repetitive research and boilerplate implementation that used to consume so much of our time, freeing us to focus on the problems that actually require human creativity and problem-solving skills.
How many software developers write in assembly anymore? Some of us maybe, but really what it comes down to is that we don't have to. We've abstracted away a lot of that particular knowledge set to a point where we don't need it anymore. We can write code in higher-level languages to help us get to solutions more quickly. If that's the case, why shouldn't we use LLMs to help us get to solutions even more quickly?
I've noticed a tendency to view LLM-assisted coding as somehow less legitimate, but this misses the opportunity to help developers integrate these tools thoughtfully into their workflow. Instead of questioning the validity of using these tools, we should be focusing on how we can help people learn to use them effectively.
In the same way that we helped people to learn how to use Google, we should help them to use large language models. Back in the early 2000s when Google was just starting to become a thing, knowing how to effectively use it to exclude specific terms, search for exact phrases using quotation marks, that wasn't always known by everybody. But the people who knew how to do that were able to find things more effectively.
I see a parallel here. Instead of dismissing people who use these tools, we should be asking more constructive questions: How do we help them become more effective with LLMs? How do we help them use these tools to actually learn and grow as developers?
Understanding the limitations of large language models is crucial to using them well, but right now we're missing that opportunity by focusing on whether people should use them at all rather than how they can use them better.
We need to take a step back and re-evaluate how we use LLMs and how we encourage others to use them. The goal is getting to a point where we understand that LLMs are one more tool in our developer toolkit, regardless of whether we're working on open-source projects or commercial software. We don't need to avoid these tools. We just need to learn how to use them more effectively, and we need to do this quickly.
Updated TIL
While browsing Mastodon the other day I came across a toot that linked to this Cursed Knowledge page. I thought it was a great page, but it occurred to me that it could be helpful to apply the same sort of styling to my TIL Repo.
My TIL (Today I Learned) repository was inspired by Simon Wilison's and is basically a rip off completely inspired by him.
Now, I'm not a front end guy, and while I can do some pretty basic stuff with GitHub Actions, I knew that what I wanted to do far outstripped my current capabilities. Enter Claude!
I started with this prompt
You are an expert in GitHub Actions, and GitHub. Additionally, you are an expert in HTML, CSS, and JavaScript. The solutions provided can not leverage JavaScript frameworks.
I then made this request
I currently have a Today I learned (TIL) repository on GitHub located here
https://github.com/ryancheley/til
I came across the idea of documenting cursed information here
https://immich.app/cursed-knowledge/
I would like to implement my TIL in a timeline the same way the cursed knowledge page was done.
How can I do that?
It output this
name: Build TIL Timeline
on:
push:
branches: [ main ]
pull_request:
branches: [ main ]
schedule:
# Rebuild daily at 6 AM UTC
- cron: '0 6 * * *'
permissions:
contents: read
pages: write
id-token: write
jobs:
build-timeline:
runs-on: ubuntu-latest
steps:
- name: Checkout repository
uses: actions/checkout@v4
- name: Setup Node.js
uses: actions/setup-node@v4
with:
node-version: '18'
- name: Generate timeline data
run: |
node << 'EOF'
const fs = require('fs');
const path = require('path');
// Function to extract metadata from markdown files
function extractTilData(filePath, content) {
const relativePath = path.relative('.', filePath);
const fileName = path.basename(filePath, '.md');
// Extract title from first heading or use filename
const titleMatch = content.match(/^#\s+(.+)$/m);
const title = titleMatch ? titleMatch[1] : fileName.replace(/[-_]/g, ' ');
// Extract first paragraph as description
const lines = content.split('\n').filter(line => line.trim());
let description = '';
for (const line of lines) {
if (!line.startsWith('#') && line.trim() && !line.startsWith('```')) {
description = line.trim();
break;
}
}
// Get file stats for date
const stats = fs.statSync(filePath);
const date = stats.mtime; // Use modification time
// Extract category from directory structure
const pathParts = relativePath.split('/');
const category = pathParts.length > 1 ? pathParts[0] : 'General';
return {
title,
description: description || 'No description available',
date: date.toISOString().split('T')[0], // YYYY-MM-DD format
url: `https://github.com/ryancheley/til/blob/main/${relativePath}`,
category,
fileName: relativePath
};
}
// Recursively find all markdown files
function findMarkdownFiles(dir) {
const files = [];
const entries = fs.readdirSync(dir, { withFileTypes: true });
for (const entry of entries) {
const fullPath = path.join(dir, entry.name);
if (entry.isDirectory() && !entry.name.startsWith('.')) {
files.push(...findMarkdownFiles(fullPath));
} else if (entry.isFile() && entry.name.endsWith('.md') && entry.name !== 'README.md') {
files.push(fullPath);
}
}
return files;
}
// Generate timeline data
const markdownFiles = findMarkdownFiles('.');
const tilEntries = [];
for (const filePath of markdownFiles) {
try {
const content = fs.readFileSync(filePath, 'utf8');
const tilData = extractTilData(filePath, content);
tilEntries.push(tilData);
} catch (error) {
console.error(`Error processing ${filePath}:`, error.message);
}
}
// Sort by date (newest first)
tilEntries.sort((a, b) => new Date(b.date) - new Date(a.date));
// Create output directory
if (!fs.existsSync('docs')) {
fs.mkdirSync('docs');
}
// Write timeline data
fs.writeFileSync('docs/timeline-data.json', JSON.stringify(tilEntries, null, 2));
console.log(`Generated timeline with ${tilEntries.length} entries`);
EOF
- name: Generate timeline HTML
run: |
mkdir -p docs
cat > docs/index.html << 'EOF'
<!DOCTYPE html>
<html lang="en">
<head>
<meta charset="UTF-8">
<meta name="viewport" content="width=device-width, initial-scale=1.0">
<title>Ryan's Today I Learned Timeline</title>
<style>
* {
margin: 0;
padding: 0;
box-sizing: border-box;
}
body {
font-family: -apple-system, BlinkMacSystemFont, 'Segoe UI', system-ui, sans-serif;
background: linear-gradient(135deg, #667eea 0%, #764ba2 100%);
min-height: 100vh;
color: #333;
}
.container {
max-width: 1200px;
margin: 0 auto;
padding: 2rem;
}
.header {
text-align: center;
margin-bottom: 3rem;
color: white;
}
.header h1 {
font-size: 3rem;
margin-bottom: 1rem;
text-shadow: 2px 2px 4px rgba(0,0,0,0.3);
}
.header p {
font-size: 1.2rem;
opacity: 0.9;
max-width: 600px;
margin: 0 auto;
}
.timeline {
position: relative;
margin-top: 2rem;
}
.timeline::before {
content: '';
position: absolute;
left: 2rem;
top: 0;
bottom: 0;
width: 2px;
background: linear-gradient(to bottom, #4CAF50, #2196F3, #FF9800, #E91E63);
}
.timeline-item {
position: relative;
margin-bottom: 2rem;
margin-left: 4rem;
background: white;
border-radius: 12px;
padding: 1.5rem;
box-shadow: 0 8px 25px rgba(0,0,0,0.1);
transition: transform 0.3s ease, box-shadow 0.3s ease;
}
.timeline-item:hover {
transform: translateY(-5px);
box-shadow: 0 15px 35px rgba(0,0,0,0.15);
}
.timeline-item::before {
content: '';
position: absolute;
left: -3rem;
top: 2rem;
width: 16px;
height: 16px;
background: #4CAF50;
border: 3px solid white;
border-radius: 50%;
box-shadow: 0 0 0 3px rgba(76, 175, 80, 0.3);
}
.timeline-item:nth-child(4n+2)::before { background: #2196F3; box-shadow: 0 0 0 3px rgba(33, 150, 243, 0.3); }
.timeline-item:nth-child(4n+3)::before { background: #FF9800; box-shadow: 0 0 0 3px rgba(255, 152, 0, 0.3); }
.timeline-item:nth-child(4n+4)::before { background: #E91E63; box-shadow: 0 0 0 3px rgba(233, 30, 99, 0.3); }
.timeline-header {
display: flex;
justify-content: space-between;
align-items: flex-start;
margin-bottom: 1rem;
flex-wrap: wrap;
gap: 1rem;
}
.timeline-title {
font-size: 1.4rem;
font-weight: 600;
color: #2c3e50;
text-decoration: none;
flex-grow: 1;
transition: color 0.3s ease;
}
.timeline-title:hover {
color: #3498db;
}
.timeline-meta {
display: flex;
gap: 1rem;
align-items: center;
flex-shrink: 0;
}
.timeline-date {
background: linear-gradient(135deg, #667eea, #764ba2);
color: white;
padding: 0.5rem 1rem;
border-radius: 20px;
font-size: 0.9rem;
font-weight: 500;
}
.timeline-category {
background: #f8f9fa;
color: #6c757d;
padding: 0.4rem 0.8rem;
border-radius: 15px;
font-size: 0.8rem;
font-weight: 500;
border: 1px solid #e9ecef;
}
.timeline-description {
color: #5a6c7d;
line-height: 1.6;
font-size: 1rem;
}
.loading {
text-align: center;
padding: 3rem;
color: white;
font-size: 1.2rem;
}
.error {
background: #f8d7da;
color: #721c24;
padding: 1rem;
border-radius: 8px;
border: 1px solid #f5c6cb;
margin-bottom: 2rem;
}
.stats {
background: rgba(255,255,255,0.95);
border-radius: 12px;
padding: 1.5rem;
margin-bottom: 2rem;
backdrop-filter: blur(10px);
border: 1px solid rgba(255,255,255,0.2);
}
.stats-grid {
display: grid;
grid-template-columns: repeat(auto-fit, minmax(200px, 1fr));
gap: 1rem;
text-align: center;
}
.stat-item {
padding: 1rem;
}
.stat-number {
font-size: 2rem;
font-weight: bold;
color: #667eea;
display: block;
}
.stat-label {
color: #666;
font-size: 0.9rem;
margin-top: 0.5rem;
}
@media (max-width: 768px) {
.container {
padding: 1rem;
}
.header h1 {
font-size: 2rem;
}
.timeline::before {
left: 1rem;
}
.timeline-item {
margin-left: 2rem;
padding: 1rem;
}
.timeline-item::before {
left: -2rem;
}
.timeline-header {
flex-direction: column;
align-items: stretch;
}
.timeline-meta {
justify-content: space-between;
}
}
</style>
</head>
<body>
<div class="container">
<div class="header">
<h1>Today I Learned</h1>
<p>A timeline of discoveries, learnings, and insights from my development journey</p>
</div>
<div class="stats" id="stats" style="display: none;">
<div class="stats-grid">
<div class="stat-item">
<span class="stat-number" id="totalEntries">0</span>
<div class="stat-label">Total Entries</div>
</div>
<div class="stat-item">
<span class="stat-number" id="categoriesCount">0</span>
<div class="stat-label">Categories</div>
</div>
<div class="stat-item">
<span class="stat-number" id="latestEntry">-</span>
<div class="stat-label">Latest Entry</div>
</div>
</div>
</div>
<div class="loading" id="loading">Loading timeline...</div>
<div class="error" id="error" style="display: none;"></div>
<div class="timeline" id="timeline"></div>
</div>
<script>
async function loadTimeline() {
try {
const response = await fetch('timeline-data.json');
if (!response.ok) {
throw new Error('Failed to load timeline data');
}
const entries = await response.json();
displayTimeline(entries);
displayStats(entries);
} catch (error) {
console.error('Error loading timeline:', error);
document.getElementById('loading').style.display = 'none';
document.getElementById('error').style.display = 'block';
document.getElementById('error').textContent = 'Failed to load timeline. Please try again later.';
}
}
function displayStats(entries) {
const categories = [...new Set(entries.map(entry => entry.category))];
const latest = entries.length > 0 ? new Date(entries[0].date).toLocaleDateString() : '-';
document.getElementById('totalEntries').textContent = entries.length;
document.getElementById('categoriesCount').textContent = categories.length;
document.getElementById('latestEntry').textContent = latest;
document.getElementById('stats').style.display = 'block';
}
function displayTimeline(entries) {
const timelineContainer = document.getElementById('timeline');
const loading = document.getElementById('loading');
loading.style.display = 'none';
if (entries.length === 0) {
timelineContainer.innerHTML = '<p style="text-align: center; color: white;">No entries found.</p>';
return;
}
const timelineHTML = entries.map(entry => {
const date = new Date(entry.date).toLocaleDateString('en-US', {
year: 'numeric',
month: 'short',
day: 'numeric'
});
return `
<div class="timeline-item">
<div class="timeline-header">
<a href="${entry.url}" class="timeline-title" target="_blank" rel="noopener noreferrer">
${entry.title}
</a>
<div class="timeline-meta">
<span class="timeline-category">${entry.category}</span>
<span class="timeline-date">${date}</span>
</div>
</div>
<div class="timeline-description">
${entry.description}
</div>
</div>
`;
}).join('');
timelineContainer.innerHTML = timelineHTML;
}
// Load timeline on page load
loadTimeline();
</script>
</body>
</html>
EOF
- name: Setup Pages
uses: actions/configure-pages@v4
- name: Upload artifact
uses: actions/upload-pages-artifact@v3
with:
path: 'docs'
deploy:
environment:
name: github-pages
url: ${{ steps.deployment.outputs.page_url }}
runs-on: ubuntu-latest
needs: build-timeline
if: github.ref == 'refs/heads/main'
steps:
- name: Deploy to GitHub Pages
id: deployment
uses: actions/deploy-pages@v4
I added it to my TIL repo and tested to see how it looked. It was a great start!
I then followed up with
this is a great start! however, it looks like the are a few issues: 1. All of the dates on the timeline are the published date and not the date of the actual learning. There is a SQLite database that stores this kind of meta data 2. The order of the items matches the order they are displayed on the Read Me, which is by category and not by date (see point 1) 3. the colors for each TIL seem to just rotate in order and aren't associated with any specific category of TIL
Claude went to work and generated a new GitHub Action for me
name: Build TIL Timeline
on:
push:
branches: [ main ]
pull_request:
branches: [ main ]
schedule:
# Rebuild daily at 6 AM UTC
- cron: '0 6 * * *'
permissions:
contents: read
pages: write
id-token: write
jobs:
build-timeline:
runs-on: ubuntu-latest
steps:
- name: Check out repo
uses: actions/checkout@v4
with:
fetch-depth: 0 # Need full history for git analysis
- name: Set up Python
uses: actions/setup-python@v5
with:
python-version: 3.12
- uses: actions/cache@v4
name: Configure pip caching
with:
path: ~/.cache/pip
key: ${{ runner.os }}-pip-${{ hashFiles('**/requirements.txt') }}
restore-keys: |
${{ runner.os }}-pip-
- name: Install Python dependencies
run: |
python -m pip install --upgrade pip
pip install -r requirements.txt
- name: Build database
run: python build_database.py
- name: Generate timeline data from SQLite
run: |
python << 'EOF'
import sqlite3
import json
import os
from pathlib import Path
# Connect to the SQLite database
db_path = Path("tils.db")
if not db_path.exists():
print("Database not found!")
exit(1)
conn = sqlite3.connect(db_path)
conn.row_factory = sqlite3.Row # Enable dict-like access to rows
# Query all TIL entries, ordered by created date (actual learning date)
cursor = conn.execute("""
SELECT
path,
slug,
topic,
title,
url,
body,
created,
created_utc,
updated,
updated_utc
FROM til
ORDER BY created_utc DESC
""")
entries = []
for row in cursor:
# Extract first paragraph as description, excluding headers and code blocks
lines = row['body'].split('\n')
description = ''
for line in lines:
line = line.strip()
if line and not line.startswith('#') and not line.startswith('```') and line != '---':
description = line
break
# Clean up the description
if len(description) > 200:
description = description[:200] + '...'
# Extract date from created_utc (YYYY-MM-DD format)
created_date = row['created_utc'].split('T')[0] if row['created_utc'] else row['created'].split('T')[0]
entry = {
'title': row['title'],
'description': description or 'No description available',
'date': created_date,
'url': row['url'],
'category': row['topic'],
'fileName': row['path'].replace('_', '/'), # Convert back from slug format
'slug': row['slug']
}
entries.append(entry)
conn.close()
# Create output directory
os.makedirs('docs', exist_ok=True)
# Write timeline data
with open('docs/timeline-data.json', 'w') as f:
json.dump(entries, f, indent=2)
print(f"Generated timeline with {len(entries)} entries")
# Generate category statistics for consistent coloring
categories = {}
for entry in entries:
cat = entry['category']
if cat not in categories:
categories[cat] = len([e for e in entries if e['category'] == cat])
# Sort categories by count (most popular first) for consistent color assignment
sorted_categories = sorted(categories.items(), key=lambda x: x[1], reverse=True)
category_colors = {}
# Define a set of distinct colors for categories
color_palette = [
'#4CAF50', # Green
'#2196F3', # Blue
'#FF9800', # Orange
'#E91E63', # Pink
'#9C27B0', # Purple
'#00BCD4', # Cyan
'#FF5722', # Deep Orange
'#795548', # Brown
'#607D8B', # Blue Grey
'#FFC107', # Amber
'#8BC34A', # Light Green
'#3F51B5', # Indigo
'#F44336', # Red
'#009688', # Teal
'#CDDC39', # Lime
]
for i, (category, count) in enumerate(sorted_categories):
category_colors[category] = color_palette[i % len(color_palette)]
# Write category color mapping
with open('docs/category-colors.json', 'w') as f:
json.dump(category_colors, f, indent=2)
print(f"Generated color mapping for {len(category_colors)} categories")
EOF
- name: Generate timeline HTML
run: |
cat > docs/index.html << 'EOF'
<!DOCTYPE html>
<html lang="en">
<head>
<meta charset="UTF-8">
<meta name="viewport" content="width=device-width, initial-scale=1.0">
<title>Ryan's Today I Learned Timeline</title>
<meta name="description" content="A chronological timeline of learning discoveries from software development, featuring insights on Python, Django, SQL, and more.">
<style>
* {
margin: 0;
padding: 0;
box-sizing: border-box;
}
body {
font-family: -apple-system, BlinkMacSystemFont, 'Segoe UI', system-ui, sans-serif;
background: linear-gradient(135deg, #667eea 0%, #764ba2 100%);
min-height: 100vh;
color: #333;
}
.container {
max-width: 1200px;
margin: 0 auto;
padding: 2rem;
}
.header {
text-align: center;
margin-bottom: 3rem;
color: white;
}
.header h1 {
font-size: 3rem;
margin-bottom: 1rem;
text-shadow: 2px 2px 4px rgba(0,0,0,0.3);
}
.header p {
font-size: 1.2rem;
opacity: 0.9;
max-width: 600px;
margin: 0 auto;
}
.filters {
background: rgba(255,255,255,0.95);
border-radius: 12px;
padding: 1.5rem;
margin-bottom: 2rem;
backdrop-filter: blur(10px);
border: 1px solid rgba(255,255,255,0.2);
}
.filter-group {
display: flex;
flex-wrap: wrap;
gap: 0.5rem;
align-items: center;
}
.filter-label {
font-weight: 600;
margin-right: 1rem;
color: #666;
}
.category-filter {
padding: 0.4rem 0.8rem;
border-radius: 20px;
border: 2px solid transparent;
background: #f8f9fa;
color: #666;
cursor: pointer;
transition: all 0.3s ease;
font-size: 0.9rem;
user-select: none;
}
.category-filter:hover {
transform: translateY(-2px);
box-shadow: 0 4px 8px rgba(0,0,0,0.1);
}
.category-filter.active {
color: white;
border-color: currentColor;
font-weight: 600;
}
.timeline {
position: relative;
margin-top: 2rem;
}
.timeline::before {
content: '';
position: absolute;
left: 2rem;
top: 0;
bottom: 0;
width: 2px;
background: linear-gradient(to bottom, #4CAF50, #2196F3, #FF9800, #E91E63);
}
.timeline-item {
position: relative;
margin-bottom: 2rem;
margin-left: 4rem;
background: white;
border-radius: 12px;
padding: 1.5rem;
box-shadow: 0 8px 25px rgba(0,0,0,0.1);
transition: all 0.3s ease;
opacity: 1;
}
.timeline-item.hidden {
display: none;
}
.timeline-item:hover {
transform: translateY(-5px);
box-shadow: 0 15px 35px rgba(0,0,0,0.15);
}
.timeline-item::before {
content: '';
position: absolute;
left: -3rem;
top: 2rem;
width: 16px;
height: 16px;
background: var(--category-color, #4CAF50);
border: 3px solid white;
border-radius: 50%;
box-shadow: 0 0 0 3px rgba(76, 175, 80, 0.3);
}
.timeline-header {
display: flex;
justify-content: space-between;
align-items: flex-start;
margin-bottom: 1rem;
flex-wrap: wrap;
gap: 1rem;
}
.timeline-title {
font-size: 1.4rem;
font-weight: 600;
color: #2c3e50;
text-decoration: none;
flex-grow: 1;
transition: color 0.3s ease;
}
.timeline-title:hover {
color: #3498db;
}
.timeline-meta {
display: flex;
gap: 1rem;
align-items: center;
flex-shrink: 0;
}
.timeline-date {
background: linear-gradient(135deg, #667eea, #764ba2);
color: white;
padding: 0.5rem 1rem;
border-radius: 20px;
font-size: 0.9rem;
font-weight: 500;
}
.timeline-category {
background: var(--category-color, #f8f9fa);
color: white;
padding: 0.4rem 0.8rem;
border-radius: 15px;
font-size: 0.8rem;
font-weight: 500;
border: 1px solid rgba(255,255,255,0.2);
}
.timeline-description {
color: #5a6c7d;
line-height: 1.6;
font-size: 1rem;
}
.loading {
text-align: center;
padding: 3rem;
color: white;
font-size: 1.2rem;
}
.error {
background: #f8d7da;
color: #721c24;
padding: 1rem;
border-radius: 8px;
border: 1px solid #f5c6cb;
margin-bottom: 2rem;
}
.stats {
background: rgba(255,255,255,0.95);
border-radius: 12px;
padding: 1.5rem;
margin-bottom: 2rem;
backdrop-filter: blur(10px);
border: 1px solid rgba(255,255,255,0.2);
}
.stats-grid {
display: grid;
grid-template-columns: repeat(auto-fit, minmax(200px, 1fr));
gap: 1rem;
text-align: center;
}
.stat-item {
padding: 1rem;
}
.stat-number {
font-size: 2rem;
font-weight: bold;
color: #667eea;
display: block;
}
.stat-label {
color: #666;
font-size: 0.9rem;
margin-top: 0.5rem;
}
@media (max-width: 768px) {
.container {
padding: 1rem;
}
.header h1 {
font-size: 2rem;
}
.timeline::before {
left: 1rem;
}
.timeline-item {
margin-left: 2rem;
padding: 1rem;
}
.timeline-item::before {
left: -2rem;
}
.timeline-header {
flex-direction: column;
align-items: stretch;
}
.timeline-meta {
justify-content: space-between;
}
.filter-group {
flex-direction: column;
align-items: stretch;
gap: 1rem;
}
.category-filter {
text-align: center;
}
}
</style>
</head>
<body>
<div class="container">
<div class="header">
<h1>Today I Learned</h1>
<p>A chronological timeline of discoveries, learnings, and insights from my development journey</p>
</div>
<div class="stats" id="stats" style="display: none;">
<div class="stats-grid">
<div class="stat-item">
<span class="stat-number" id="totalEntries">0</span>
<div class="stat-label">Total Entries</div>
</div>
<div class="stat-item">
<span class="stat-number" id="categoriesCount">0</span>
<div class="stat-label">Categories</div>
</div>
<div class="stat-item">
<span class="stat-number" id="latestEntry">-</span>
<div class="stat-label">Latest Entry</div>
</div>
<div class="stat-item">
<span class="stat-number" id="filteredCount">0</span>
<div class="stat-label">Showing</div>
</div>
</div>
</div>
<div class="filters" id="filters" style="display: none;">
<div class="filter-group">
<span class="filter-label">Filter by category:</span>
<div id="categoryFilters"></div>
</div>
</div>
<div class="loading" id="loading">Loading timeline...</div>
<div class="error" id="error" style="display: none;"></div>
<div class="timeline" id="timeline"></div>
</div>
<script>
let allEntries = [];
let categoryColors = {};
let activeCategory = null;
async function loadTimeline() {
try {
// Load timeline data and category colors
const [entriesResponse, colorsResponse] = await Promise.all([
fetch('timeline-data.json'),
fetch('category-colors.json')
]);
if (!entriesResponse.ok || !colorsResponse.ok) {
throw new Error('Failed to load timeline data');
}
allEntries = await entriesResponse.json();
categoryColors = await colorsResponse.json();
displayTimeline(allEntries);
displayStats(allEntries);
createCategoryFilters();
} catch (error) {
console.error('Error loading timeline:', error);
document.getElementById('loading').style.display = 'none';
document.getElementById('error').style.display = 'block';
document.getElementById('error').textContent = 'Failed to load timeline. Please try again later.';
}
}
function createCategoryFilters() {
const categories = [...new Set(allEntries.map(entry => entry.category))];
const filtersContainer = document.getElementById('categoryFilters');
// Add "All" filter
const allFilter = document.createElement('span');
allFilter.className = 'category-filter active';
allFilter.textContent = 'All';
allFilter.onclick = () => filterByCategory(null);
filtersContainer.appendChild(allFilter);
// Add category filters
categories.sort().forEach(category => {
const filter = document.createElement('span');
filter.className = 'category-filter';
filter.textContent = category;
filter.style.setProperty('--category-color', categoryColors[category] || '#666');
filter.onclick = () => filterByCategory(category);
filtersContainer.appendChild(filter);
});
document.getElementById('filters').style.display = 'block';
}
function filterByCategory(category) {
activeCategory = category;
// Update filter button states
document.querySelectorAll('.category-filter').forEach(filter => {
filter.classList.remove('active');
if ((category === null && filter.textContent === 'All') ||
filter.textContent === category) {
filter.classList.add('active');
if (category !== null) {
filter.style.background = categoryColors[category];
}
}
});
// Filter timeline items
const filteredEntries = category ?
allEntries.filter(entry => entry.category === category) :
allEntries;
displayTimeline(filteredEntries);
updateFilteredCount(filteredEntries.length);
}
function updateFilteredCount(count) {
document.getElementById('filteredCount').textContent = count;
}
function displayStats(entries) {
const categories = [...new Set(entries.map(entry => entry.category))];
const latest = entries.length > 0 ? new Date(entries[0].date).toLocaleDateString() : '-';
document.getElementById('totalEntries').textContent = entries.length;
document.getElementById('categoriesCount').textContent = categories.length;
document.getElementById('latestEntry').textContent = latest;
document.getElementById('filteredCount').textContent = entries.length;
document.getElementById('stats').style.display = 'block';
}
function displayTimeline(entries) {
const timelineContainer = document.getElementById('timeline');
const loading = document.getElementById('loading');
loading.style.display = 'none';
if (entries.length === 0) {
timelineContainer.innerHTML = '<p style="text-align: center; color: white;">No entries found.</p>';
return;
}
const timelineHTML = entries.map(entry => {
const date = new Date(entry.date).toLocaleDateString('en-US', {
year: 'numeric',
month: 'short',
day: 'numeric'
});
const categoryColor = categoryColors[entry.category] || '#666';
return `
<div class="timeline-item" style="--category-color: ${categoryColor}">
<div class="timeline-header">
<a href="${entry.url}" class="timeline-title" target="_blank" rel="noopener noreferrer">
${entry.title}
</a>
<div class="timeline-meta">
<span class="timeline-category" style="--category-color: ${categoryColor}; background: ${categoryColor};">
${entry.category}
</span>
<span class="timeline-date">${date}</span>
</div>
</div>
<div class="timeline-description">
${entry.description}
</div>
</div>
`;
}).join('');
timelineContainer.innerHTML = timelineHTML;
}
// Load timeline on page load
loadTimeline();
</script>
</body>
</html>
EOF
- name: Setup Pages
uses: actions/configure-pages@v4
- name: Upload artifact
uses: actions/upload-pages-artifact@v3
with:
path: 'docs'
deploy:
environment:
name: github-pages
url: ${{ steps.deployment.outputs.page_url }}
runs-on: ubuntu-latest
needs: build-timeline
if: github.ref == 'refs/heads/main'
steps:
- name: Deploy to GitHub Pages
id: deployment
uses: actions/deploy-pages@v4
Another huge step forward! However, there was one last change that was needed
oh wow! much better! The last issue I'm seeing is that because I have so many categories, the Filter by category needs a way to wrap based on the page width. Right now it's on a single line, but would likely benefit from a css style that will wrap the lines
And I got this
name: Build TIL Timeline
on:
push:
branches: [ main ]
pull_request:
branches: [ main ]
schedule:
# Rebuild daily at 6 AM UTC
- cron: '0 6 * * *'
permissions:
contents: read
pages: write
id-token: write
jobs:
build-timeline:
runs-on: ubuntu-latest
steps:
- name: Check out repo
uses: actions/checkout@v4
with:
fetch-depth: 0 # Need full history for git analysis
- name: Set up Python
uses: actions/setup-python@v5
with:
python-version: 3.12
- uses: actions/cache@v4
name: Configure pip caching
with:
path: ~/.cache/pip
key: ${{ runner.os }}-pip-${{ hashFiles('**/requirements.txt') }}
restore-keys: |
${{ runner.os }}-pip-
- name: Install Python dependencies
run: |
python -m pip install --upgrade pip
pip install -r requirements.txt
- name: Build database
run: python build_database.py
- name: Generate timeline data from SQLite
run: |
python << 'EOF'
import sqlite3
import json
import os
from pathlib import Path
# Connect to the SQLite database
db_path = Path("tils.db")
if not db_path.exists():
print("Database not found!")
exit(1)
conn = sqlite3.connect(db_path)
conn.row_factory = sqlite3.Row # Enable dict-like access to rows
# Query all TIL entries, ordered by created date (actual learning date)
cursor = conn.execute("""
SELECT
path,
slug,
topic,
title,
url,
body,
created,
created_utc,
updated,
updated_utc
FROM til
ORDER BY created_utc DESC
""")
entries = []
for row in cursor:
# Extract first paragraph as description, excluding headers and code blocks
lines = row['body'].split('\n')
description = ''
for line in lines:
line = line.strip()
if line and not line.startswith('#') and not line.startswith('```') and line != '---':
description = line
break
# Clean up the description
if len(description) > 200:
description = description[:200] + '...'
# Extract date from created_utc (YYYY-MM-DD format)
created_date = row['created_utc'].split('T')[0] if row['created_utc'] else row['created'].split('T')[0]
entry = {
'title': row['title'],
'description': description or 'No description available',
'date': created_date,
'url': row['url'],
'category': row['topic'],
'fileName': row['path'].replace('_', '/'), # Convert back from slug format
'slug': row['slug']
}
entries.append(entry)
conn.close()
# Create output directory
os.makedirs('docs', exist_ok=True)
# Write timeline data
with open('docs/timeline-data.json', 'w') as f:
json.dump(entries, f, indent=2)
print(f"Generated timeline with {len(entries)} entries")
# Generate category statistics for consistent coloring
categories = {}
for entry in entries:
cat = entry['category']
if cat not in categories:
categories[cat] = len([e for e in entries if e['category'] == cat])
# Sort categories by count (most popular first) for consistent color assignment
sorted_categories = sorted(categories.items(), key=lambda x: x[1], reverse=True)
category_colors = {}
# Define a set of distinct colors for categories
color_palette = [
'#4CAF50', # Green
'#2196F3', # Blue
'#FF9800', # Orange
'#E91E63', # Pink
'#9C27B0', # Purple
'#00BCD4', # Cyan
'#FF5722', # Deep Orange
'#795548', # Brown
'#607D8B', # Blue Grey
'#FFC107', # Amber
'#8BC34A', # Light Green
'#3F51B5', # Indigo
'#F44336', # Red
'#009688', # Teal
'#CDDC39', # Lime
]
for i, (category, count) in enumerate(sorted_categories):
category_colors[category] = color_palette[i % len(color_palette)]
# Write category color mapping
with open('docs/category-colors.json', 'w') as f:
json.dump(category_colors, f, indent=2)
print(f"Generated color mapping for {len(category_colors)} categories")
EOF
- name: Generate timeline HTML
run: |
cat > docs/index.html << 'EOF'
<!DOCTYPE html>
<html lang="en">
<head>
<meta charset="UTF-8">
<meta name="viewport" content="width=device-width, initial-scale=1.0">
<title>Ryan's Today I Learned Timeline</title>
<meta name="description" content="A chronological timeline of learning discoveries from software development, featuring insights on Python, Django, SQL, and more.">
<style>
* {
margin: 0;
padding: 0;
box-sizing: border-box;
}
body {
font-family: -apple-system, BlinkMacSystemFont, 'Segoe UI', system-ui, sans-serif;
background: linear-gradient(135deg, #667eea 0%, #764ba2 100%);
min-height: 100vh;
color: #333;
}
.container {
max-width: 1200px;
margin: 0 auto;
padding: 2rem;
}
.header {
text-align: center;
margin-bottom: 3rem;
color: white;
}
.header h1 {
font-size: 3rem;
margin-bottom: 1rem;
text-shadow: 2px 2px 4px rgba(0,0,0,0.3);
}
.header p {
font-size: 1.2rem;
opacity: 0.9;
max-width: 600px;
margin: 0 auto;
}
.filters {
background: rgba(255,255,255,0.95);
border-radius: 12px;
padding: 1.5rem;
margin-bottom: 2rem;
backdrop-filter: blur(10px);
border: 1px solid rgba(255,255,255,0.2);
}
.filter-group {
display: flex;
flex-direction: column;
gap: 1rem;
}
.filter-label {
font-weight: 600;
color: #666;
margin-bottom: 0.5rem;
}
.category-filters-container {
display: flex;
flex-wrap: wrap;
gap: 0.5rem;
align-items: center;
}
.category-filter {
padding: 0.4rem 0.8rem;
border-radius: 20px;
border: 2px solid transparent;
background: #f8f9fa;
color: #666;
cursor: pointer;
transition: all 0.3s ease;
font-size: 0.9rem;
user-select: none;
}
.category-filter:hover {
transform: translateY(-2px);
box-shadow: 0 4px 8px rgba(0,0,0,0.1);
}
.category-filter.active {
color: white;
border-color: currentColor;
font-weight: 600;
}
.timeline {
position: relative;
margin-top: 2rem;
}
.timeline::before {
content: '';
position: absolute;
left: 2rem;
top: 0;
bottom: 0;
width: 2px;
background: linear-gradient(to bottom, #4CAF50, #2196F3, #FF9800, #E91E63);
}
.timeline-item {
position: relative;
margin-bottom: 2rem;
margin-left: 4rem;
background: white;
border-radius: 12px;
padding: 1.5rem;
box-shadow: 0 8px 25px rgba(0,0,0,0.1);
transition: all 0.3s ease;
opacity: 1;
}
.timeline-item.hidden {
display: none;
}
.timeline-item:hover {
transform: translateY(-5px);
box-shadow: 0 15px 35px rgba(0,0,0,0.15);
}
.timeline-item::before {
content: '';
position: absolute;
left: -3rem;
top: 2rem;
width: 16px;
height: 16px;
background: var(--category-color, #4CAF50);
border: 3px solid white;
border-radius: 50%;
box-shadow: 0 0 0 3px rgba(76, 175, 80, 0.3);
}
.timeline-header {
display: flex;
justify-content: space-between;
align-items: flex-start;
margin-bottom: 1rem;
flex-wrap: wrap;
gap: 1rem;
}
.timeline-title {
font-size: 1.4rem;
font-weight: 600;
color: #2c3e50;
text-decoration: none;
flex-grow: 1;
transition: color 0.3s ease;
}
.timeline-title:hover {
color: #3498db;
}
.timeline-meta {
display: flex;
gap: 1rem;
align-items: center;
flex-shrink: 0;
}
.timeline-date {
background: linear-gradient(135deg, #667eea, #764ba2);
color: white;
padding: 0.5rem 1rem;
border-radius: 20px;
font-size: 0.9rem;
font-weight: 500;
}
.timeline-category {
background: var(--category-color, #f8f9fa);
color: white;
padding: 0.4rem 0.8rem;
border-radius: 15px;
font-size: 0.8rem;
font-weight: 500;
border: 1px solid rgba(255,255,255,0.2);
}
.timeline-description {
color: #5a6c7d;
line-height: 1.6;
font-size: 1rem;
}
.loading {
text-align: center;
padding: 3rem;
color: white;
font-size: 1.2rem;
}
.error {
background: #f8d7da;
color: #721c24;
padding: 1rem;
border-radius: 8px;
border: 1px solid #f5c6cb;
margin-bottom: 2rem;
}
.stats {
background: rgba(255,255,255,0.95);
border-radius: 12px;
padding: 1.5rem;
margin-bottom: 2rem;
backdrop-filter: blur(10px);
border: 1px solid rgba(255,255,255,0.2);
}
.stats-grid {
display: grid;
grid-template-columns: repeat(auto-fit, minmax(200px, 1fr));
gap: 1rem;
text-align: center;
}
.stat-item {
padding: 1rem;
}
.stat-number {
font-size: 2rem;
font-weight: bold;
color: #667eea;
display: block;
}
.stat-label {
color: #666;
font-size: 0.9rem;
margin-top: 0.5rem;
}
@media (max-width: 768px) {
.container {
padding: 1rem;
}
.header h1 {
font-size: 2rem;
}
.timeline::before {
left: 1rem;
}
.timeline-item {
margin-left: 2rem;
padding: 1rem;
}
.timeline-item::before {
left: -2rem;
}
.timeline-header {
flex-direction: column;
align-items: stretch;
}
.timeline-meta {
justify-content: space-between;
}
.filter-group {
gap: 1rem;
}
.category-filters-container {
justify-content: center;
}
}
</style>
</head>
<body>
<div class="container">
<div class="header">
<h1>Today I Learned</h1>
<p>A chronological timeline of discoveries, learnings, and insights from my development journey</p>
</div>
<div class="stats" id="stats" style="display: none;">
<div class="stats-grid">
<div class="stat-item">
<span class="stat-number" id="totalEntries">0</span>
<div class="stat-label">Total Entries</div>
</div>
<div class="stat-item">
<span class="stat-number" id="categoriesCount">0</span>
<div class="stat-label">Categories</div>
</div>
<div class="stat-item">
<span class="stat-number" id="latestEntry">-</span>
<div class="stat-label">Latest Entry</div>
</div>
<div class="stat-item">
<span class="stat-number" id="filteredCount">0</span>
<div class="stat-label">Showing</div>
</div>
</div>
</div>
<div class="filters" id="filters" style="display: none;">
<div class="filter-group">
<span class="filter-label">Filter by category:</span>
<div class="category-filters-container" id="categoryFilters"></div>
</div>
</div>
<div class="loading" id="loading">Loading timeline...</div>
<div class="error" id="error" style="display: none;"></div>
<div class="timeline" id="timeline"></div>
</div>
<script>
let allEntries = [];
let categoryColors = {};
let activeCategory = null;
async function loadTimeline() {
try {
// Load timeline data and category colors
const [entriesResponse, colorsResponse] = await Promise.all([
fetch('timeline-data.json'),
fetch('category-colors.json')
]);
if (!entriesResponse.ok || !colorsResponse.ok) {
throw new Error('Failed to load timeline data');
}
allEntries = await entriesResponse.json();
categoryColors = await colorsResponse.json();
displayTimeline(allEntries);
displayStats(allEntries);
createCategoryFilters();
} catch (error) {
console.error('Error loading timeline:', error);
document.getElementById('loading').style.display = 'none';
document.getElementById('error').style.display = 'block';
document.getElementById('error').textContent = 'Failed to load timeline. Please try again later.';
}
}
function createCategoryFilters() {
const categories = [...new Set(allEntries.map(entry => entry.category))];
const filtersContainer = document.getElementById('categoryFilters');
// Add "All" filter
const allFilter = document.createElement('span');
allFilter.className = 'category-filter active';
allFilter.textContent = 'All';
allFilter.onclick = () => filterByCategory(null);
filtersContainer.appendChild(allFilter);
// Add category filters
categories.sort().forEach(category => {
const filter = document.createElement('span');
filter.className = 'category-filter';
filter.textContent = category;
filter.style.setProperty('--category-color', categoryColors[category] || '#666');
filter.onclick = () => filterByCategory(category);
filtersContainer.appendChild(filter);
});
document.getElementById('filters').style.display = 'block';
}
function filterByCategory(category) {
activeCategory = category;
// Update filter button states
document.querySelectorAll('.category-filter').forEach(filter => {
filter.classList.remove('active');
if ((category === null && filter.textContent === 'All') ||
filter.textContent === category) {
filter.classList.add('active');
if (category !== null) {
filter.style.background = categoryColors[category];
}
}
});
// Filter timeline items
const filteredEntries = category ?
allEntries.filter(entry => entry.category === category) :
allEntries;
displayTimeline(filteredEntries);
updateFilteredCount(filteredEntries.length);
}
function updateFilteredCount(count) {
document.getElementById('filteredCount').textContent = count;
}
function displayStats(entries) {
const categories = [...new Set(entries.map(entry => entry.category))];
const latest = entries.length > 0 ? new Date(entries[0].date).toLocaleDateString() : '-';
document.getElementById('totalEntries').textContent = entries.length;
document.getElementById('categoriesCount').textContent = categories.length;
document.getElementById('latestEntry').textContent = latest;
document.getElementById('filteredCount').textContent = entries.length;
document.getElementById('stats').style.display = 'block';
}
function displayTimeline(entries) {
const timelineContainer = document.getElementById('timeline');
const loading = document.getElementById('loading');
loading.style.display = 'none';
if (entries.length === 0) {
timelineContainer.innerHTML = '<p style="text-align: center; color: white;">No entries found.</p>';
return;
}
const timelineHTML = entries.map(entry => {
const date = new Date(entry.date).toLocaleDateString('en-US', {
year: 'numeric',
month: 'short',
day: 'numeric'
});
const categoryColor = categoryColors[entry.category] || '#666';
return `
<div class="timeline-item" style="--category-color: ${categoryColor}">
<div class="timeline-header">
<a href="${entry.url}" class="timeline-title" target="_blank" rel="noopener noreferrer">
${entry.title}
</a>
<div class="timeline-meta">
<span class="timeline-category" style="--category-color: ${categoryColor}; background: ${categoryColor};">
${entry.category}
</span>
<span class="timeline-date">${date}</span>
</div>
</div>
<div class="timeline-description">
${entry.description}
</div>
</div>
`;
}).join('');
timelineContainer.innerHTML = timelineHTML;
}
// Load timeline on page load
loadTimeline();
</script>
</body>
</html>
EOF
- name: Setup Pages
uses: actions/configure-pages@v4
- name: Upload artifact
uses: actions/upload-pages-artifact@v3
with:
path: 'docs'
deploy:
environment:
name: github-pages
url: ${{ steps.deployment.outputs.page_url }}
runs-on: ubuntu-latest
needs: build-timeline
if: github.ref == 'refs/heads/main'
steps:
- name: Deploy to GitHub Pages
id: deployment
uses: actions/deploy-pages@v4
All told from start to finish, this took about 20 minutes. There are still some potential updates, but for 20 minutes of work I was able to take a 'wild' idea that I would have never been able to do before and had something that I'm actually excited about! And it has the added bonus of encouraging me to write more TILs because I now have this nice looking timeline of my TILs.
Fun with MCPs
Special Thanks to Jeff Triplett who provided an example that really got me started on better understanding of how this all works.
In trying to wrap my head around MCPs over the long Memorial weekend I had a breakthrough. I'm not really sure why this was so hard for me to grok, but now something seems to have clicked.
I am working with Pydantic AI and so I'll be using that as an example, but since MCPs are a standard protocol, these concepts apply broadly across different implementations.
What is Model Context Protocol (MCP)?
Per the Anthropic announcement (from November 2024!!!!)
The Model Context Protocol is an open standard that enables developers to build secure, two-way connections between their data sources and AI-powered tools. The architecture is straightforward: developers can either expose their data through MCP servers or build AI applications (MCP clients) that connect to these servers.
What this means is that there is a standard way to extend models like Claude, or OpenAI to include other information. That information can be files on the file system, data in a database, etc.
(Potential) Real World Example
I work for a Healthcare organization in Southern California. One of the biggest challenges with onboarding new hires (and honestly can be a challenge for people that have been with the organization for a long time) is who to reach out to for support on which specific application.
Typically a user will send an email to one of the support teams, and the email request can get bounced around for a while until it finally lands on the 'right' support desk. There's the potential to have the applications themselves include who to contact, but some applications are vendor supplied and there isn't always a way to do that.
Even if there were, in my experience those are often not noticed by users OR the users will think that the support email is for non-technical issues, like "Please update the phone number for this patient" and not issues like, "The web page isn't returning any results for me, but it is for my coworker."
Enter an MCP with a Local LLM
Let's say you have a service that allows you to search through a file system in a predefined set of directories. This service is run with the following command
npx -y --no-cache @modelcontextprotocol/server-filesystem /path/to/your/files
In Pydantic AI the use of the MCPServerStdio is using this same syntax only it breaks it into two parts
- command
- args
The command is any application in your $PATH like uvx or docker or npx, or you can explicitly define where the executable is by calling out its path, like /Users/ryancheley/.local/share/mise/installs/bun/latest/bin/bunx
The args are the commands you'd pass to your application.
Taking the command from above and breaking it down we can set up our MCP using the following
MCPServerStdio(
    "npx",
    args=[
        "-y",
        "--no-cache",
        "@modelcontextprotocol/server-filesystem",
        "/path/to/your/files",
    ]
Application of MCP with the Example
Since I work in Healthcare, and I want to be mindful of the protection of patient data, even if that data won't be exposed to this LLM, I'll use ollama to construct my example.
I created a support.csv file that contains the following information
- Common Name of the Application
- URL of the Application
- Support Email
- Support Extension
- Department
I used the following prompt
Review the file
support.csvand help me determine who I contact about questions related to CarePath Analytics.
Here are the contents of the support.csv file
| Name | URL | Support Email | Support Extension | Department |
|---|---|---|---|---|
| MedFlow Solutions | https://medflow.com | support@medflow.com | 1234 | Clinical Systems |
| HealthTech Portal | https://healthtech-portal.org | help@medflow.com | 3456 | Patient Services |
| CarePath Analytics | https://carepath.io | support@medflow.com | 4567 | Data Analytics |
| VitalSign Monitor | https://vitalsign.net | support@medflow.com | 1234 | Clinical Systems |
| Patient Connect Hub | https://patientconnect.com | contact@medflow.com | 3456 | Patient Services |
| EHR Bridge | https://ehrbridge.org | support@medflow.com | 2341 | Integration Services |
| Clinical Workflow Pro | https://clinicalwf.com | support@medflow.com | 1234 | Clinical Systems |
| HealthData Sync | https://healthdata-sync.net | sync@medflow.com | 6789 | Integration Services |
| TeleHealth Connect | https://telehealth-connect.com | help@medflow.com | 3456 | Patient Services |
| MedRecord Central | https://medrecord.central | records@medflow.com | 5678 | Medical Records |
The script is below:
# /// script
# requires-python = ">=3.12"
# dependencies = [
#     "pydantic-ai",
# ]
# ///

import asyncio
from pydantic_ai import Agent
from pydantic_ai.mcp import MCPServerStdio
from pydantic_ai.models.openai import OpenAIModel
from pydantic_ai.providers.openai import OpenAIProvider

async def main():
    # Configure the Ollama model using OpenAI-compatible API
    model = OpenAIModel(
        model_name='qwen3:8b',  # or whatever model you have installed locally
        provider=OpenAIProvider(base_url='http://localhost:11434/v1')
    )

    # Set up the MCP server to access our support files
    support_files_server = MCPServerStdio(
        "npx",
        args=[
            "-y",
            "@modelcontextprotocol/server-filesystem",
            "/path/to/your/files"  # Directory containing support.csv
        ]
    )

    # Create the agent with the model and MCP server
    agent = Agent(
        model=model,
        mcp_servers=[support_files_server],
    )

    # Run the agent with the MCP server
    async with agent.run_mcp_servers():
        # Get response from Ollama about support contact
        result = await agent.run(
            "Review the file `support.csv` and help me determine who I contact about questions related to CarePath Analytics?"        )
        print(result.output)

if __name__ == "__main__":
    asyncio.run(main())
As a user, if I ask, who do I contact about questions related to CarePath Analytics the LLM will search through the support.csv file and supply the email contact.
This example shows a command line script, and a Web Interface would probably be better for most users. That would be the next thing I'd try to do here.
Once that was done you could extend it to also include an MCP to write an email on the user's behalf. It could even ask probing questions to help make sure that the email had more context for the support team.
Some support systems have their own ticketing / issue tracking systems and it would be really valuable if this ticket could be written directly to that system. With the MCP this is possible.
We'd need to update the support.csv file with some information about direct writes via an API, and we'd need to secure the crap out of this, but it is possible.
Now, the user can be more confident that their issue will go to the team that it needs to and that their question / issue can be resolved much more quickly.
Uptime Kuma and Claude
While talking to a colleague of mine he had mentioned something called Uptime Kuma, which is an open source alternative to Uptime Robot. This was interesting for me because I have Uptime Robot checking a couple of my websites and I thought, "Hey, maybe I can use Uptime Kuma as a replacement for Uptime Robot."
I dove into the docs a bit and discovered that there was a Docker image for it, which was nice.
I then used Claude to take the docker run command
docker run -d \
    --restart=always \
    -p 3001:3001 \
    -v uptime-kuma:/app/data \
    --name uptime-kuma louislam/uptime-kuma:1
and turn it into a compose file, which gave me this
version: '3'

services:
  uptime-kuma:
    image: louislam/uptime-kuma:1
    container_name: uptime-kuma
    restart: always
    ports:
      - "3001:3001"
    volumes:
      - uptime-kuma:/app/data

volumes:
  uptime-kuma:
Next, I took the output of that compose file and asked Claude to also generate a caddy configuration for me and it gave me this
monitor.yourdomain.com {
    # Enable compression
    encode gzip zstd

    # Add security headers
    header {
        # Enable HSTS
        Strict-Transport-Security "max-age=31536000; includeSubDomains; preload"
        # Prevent content-type sniffing
        X-Content-Type-Options "nosniff"
        # Referrer policy
        Referrer-Policy "strict-origin-when-cross-origin"
    }

    # Reverse proxy to Uptime Kuma
    reverse_proxy localhost:3001
}
I then SSH'd into one of my servers using Shellfish 1.
I updated the docker-compose.yml file and my Caddyfile to include what Claude had output.
I restarted my docker containers and didn't get my new container running.
So I took the whole Docker Compose file from my server and I put that into Claude and said,
Hey, is there anything wrong with my Docker Compose file?
It indicated that there were some issues and provided updates for. I made those changes and did the same thing with the Caddyfile. Again, Claude offered up some changes. I applied the recommended changes for the docker-compose.yml file and the Caddyfile stopped and started my docker containers.
I suddenly had an instance of Uptime Kuma. All in all, it took about a half hour from start to finish while I was watching a hockey game ... from my iPad.
I didn't really have to do anything other than a couple of tweaks here and there on the Docker Compose file and a couple of tweaks here and there on the Caddyfile. and I suddenly have this tool that allows me to monitor the uptime of various websites that I'm interested in.
As I wrapped up it hit me ... holy crap, this is an amazing time to live2. You have an idea, Claude (or whatever AI tool you want to use) outputs a thing, and then you're up and running. This really reduces that barrier to entry to just try new things.
Is the Docker Compose file the most performant? I don't know. Is the Caddyfile the most secured lockdown thing? I don't know.
But for these small projects that are just me, I don't know how much it really matters.
Page 1 / 13